Files in the extreme range, tens or even hundreds of gigabytes, expose the weaknesses in tools not built for this scale almost immediately: attempts to open them directly fail, scripts written without streaming in mind run out of memory, and the file sits unusable until something can actually process it.
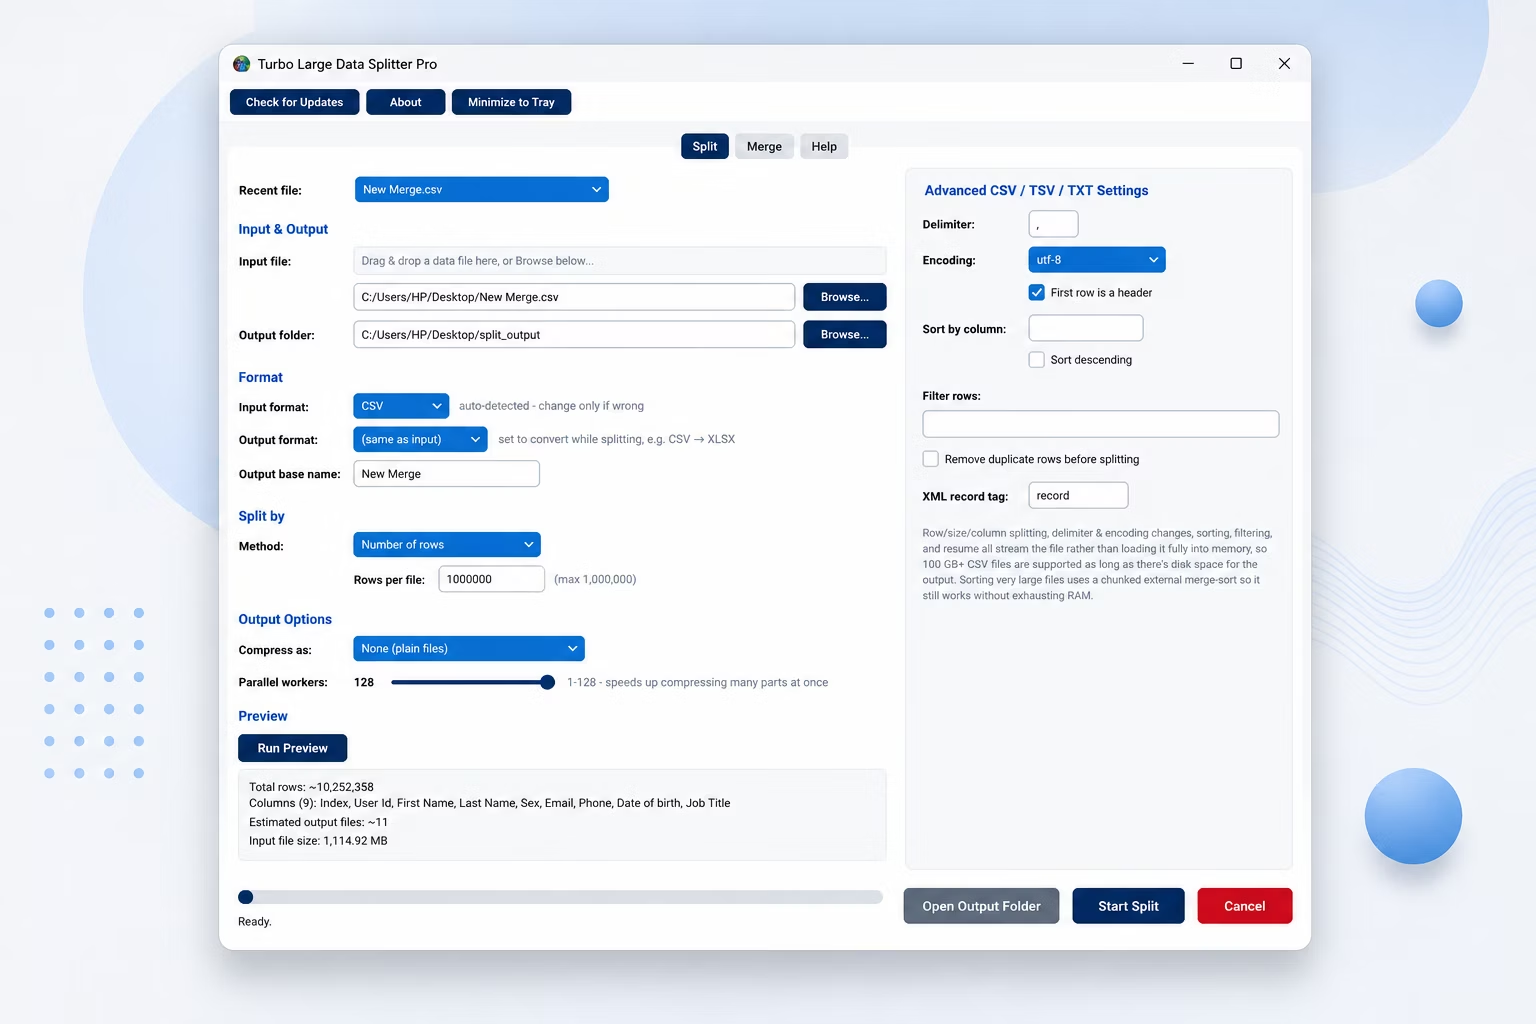
Turbo Large Data Splitter processes extremely large data files through a streaming engine that reads and writes most formats row by row rather than loading the whole file into memory, so multi-GB and even 100 GB+ files are supported as long as there's enough free disk space for the output.
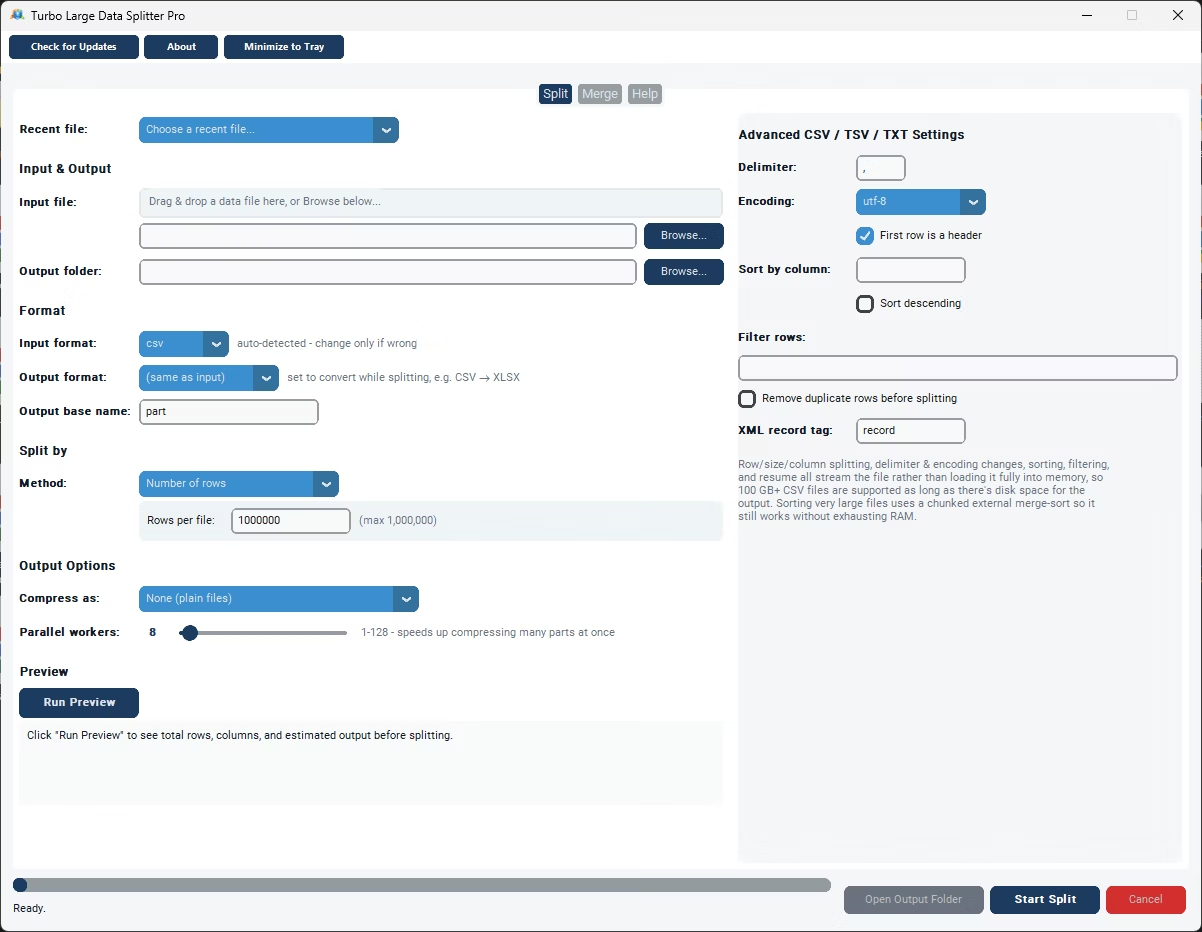
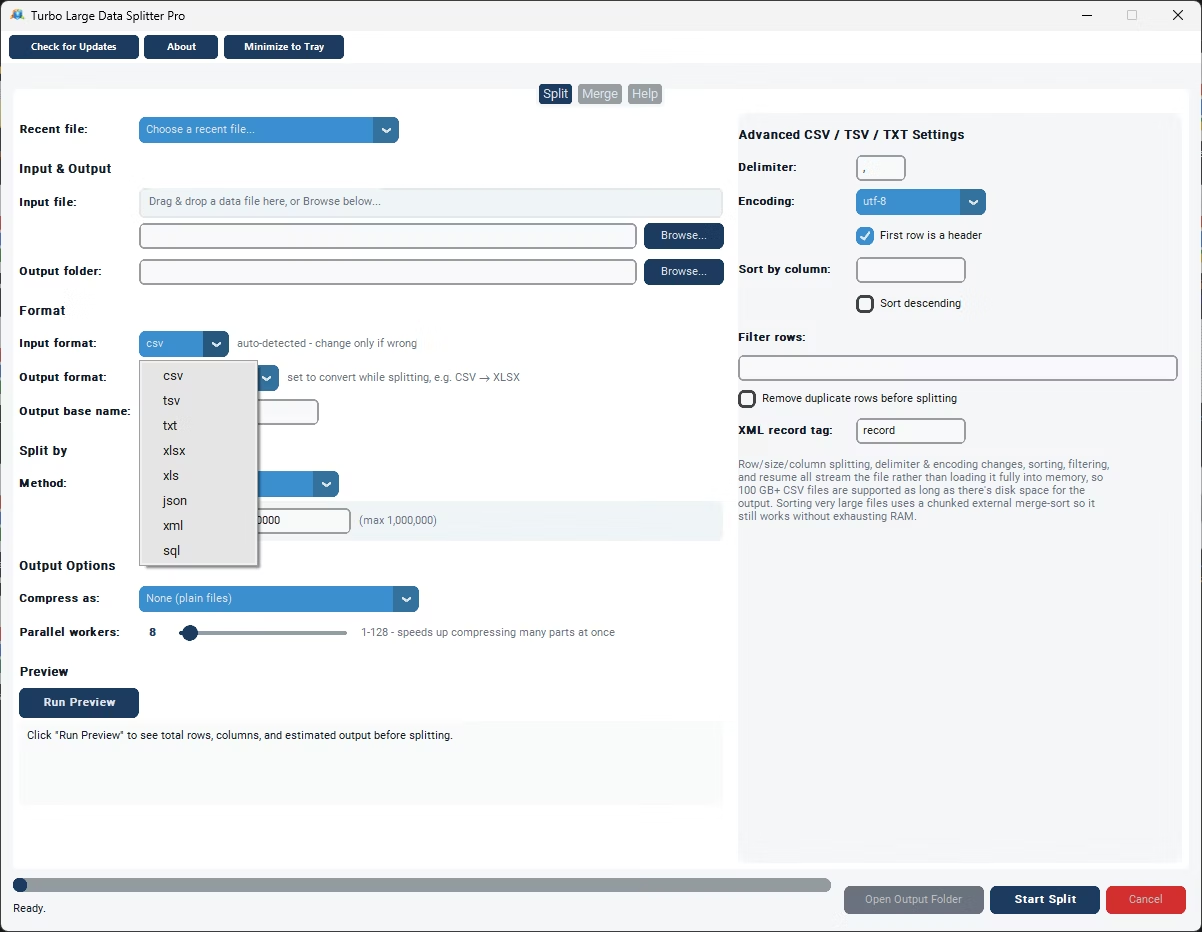
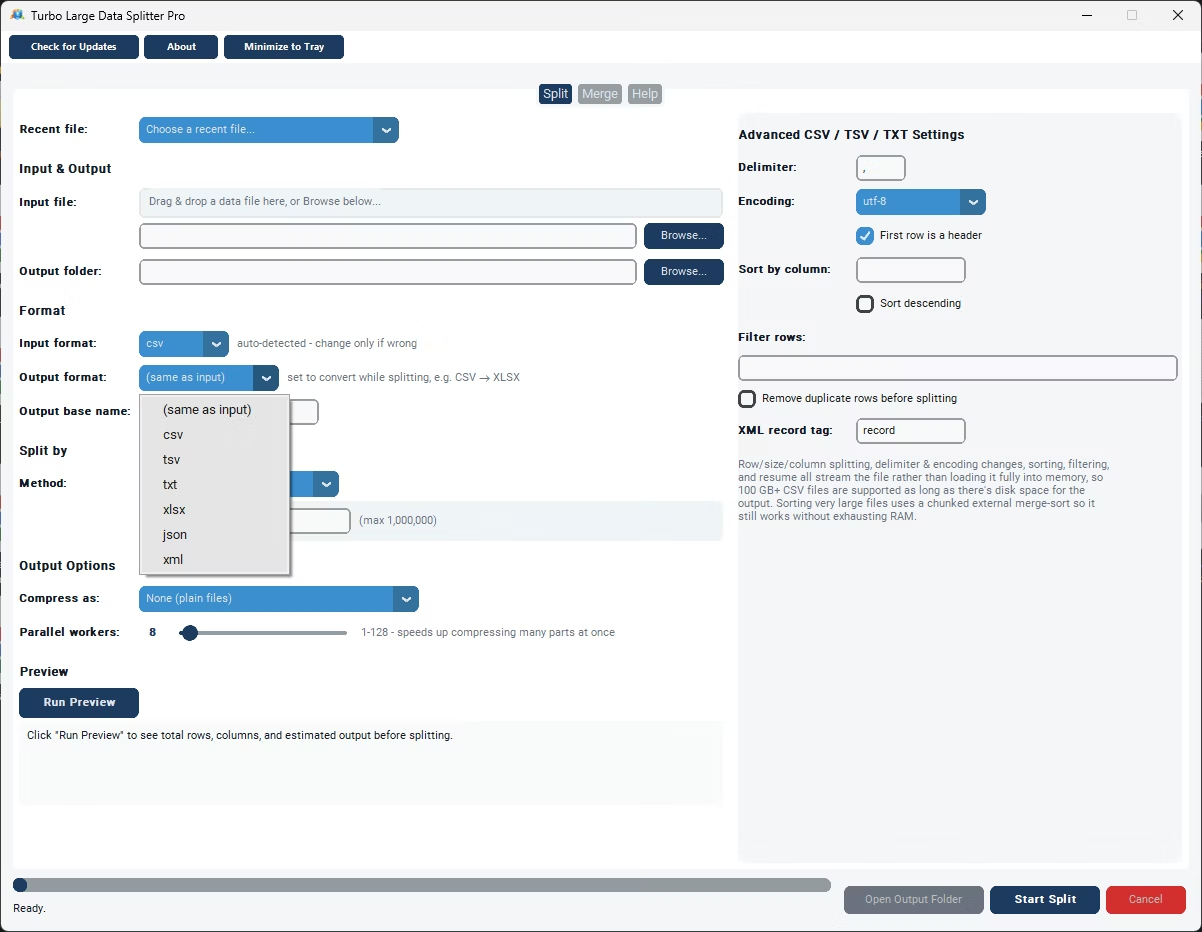
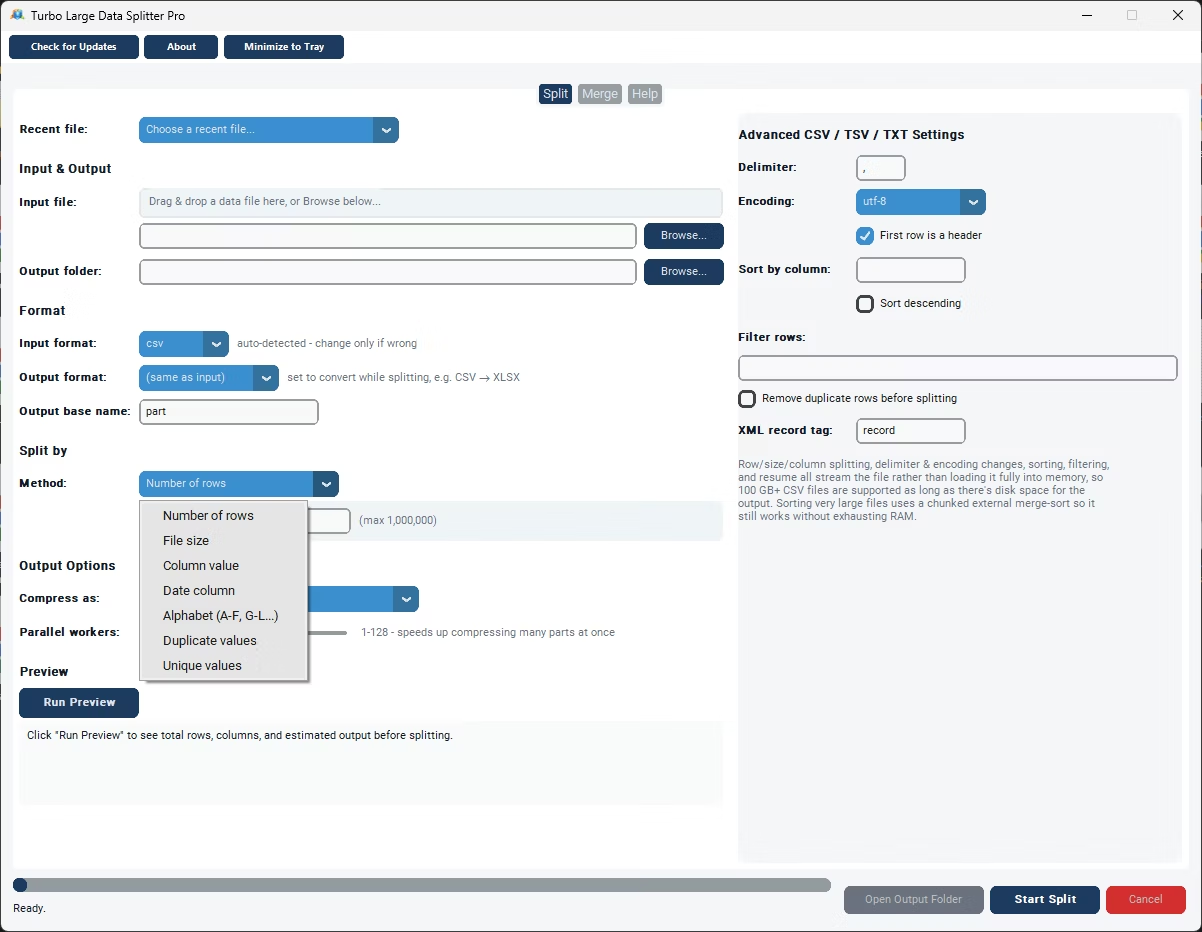
Seven split methods let you divide an extremely large file however your situation calls for, by row count, by target size, by a column's distinct values, by date period, alphabetically, or by duplicate status, across CSV, TSV, TXT, XLSX, JSON, and XML.
A live status bar tracks progress with speed and an ETA, giving you a realistic sense of how a massive job is progressing rather than watching an unresponsive screen for an unknown amount of time, which matters even more at this scale where jobs can genuinely run for hours.
If a massive split job is interrupted, whether by a cancel, a crash, or a restart, a checkpoint file saved in the output folder lets you resume exactly where the job left off, avoiding the need to reprocess data that's already been split, a critical feature when jobs at this scale take substantial time.
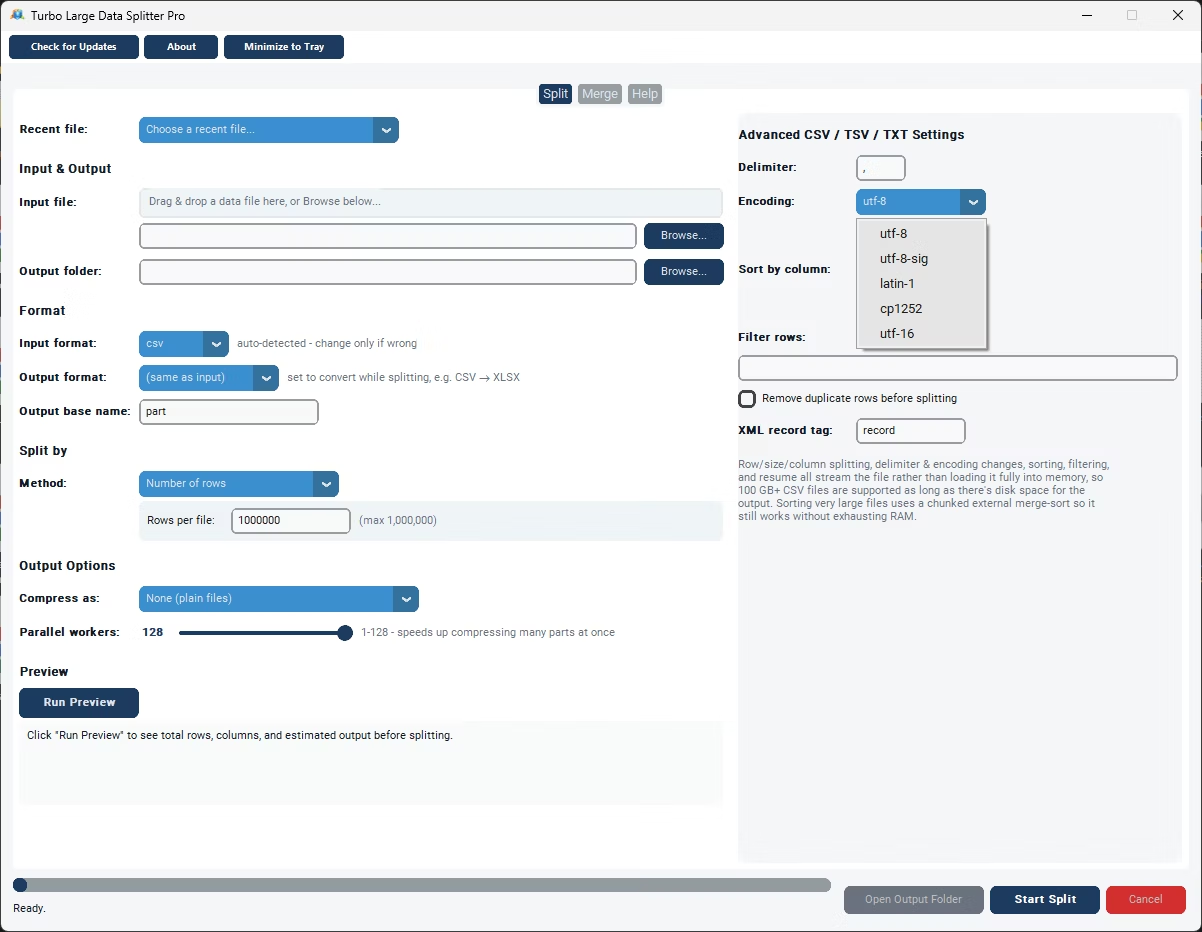
Everything runs entirely offline, on your own Windows PC, so processing an extremely large file full of potentially sensitive data never requires uploading that volume of data to an external service first. Delimiter and encoding both default to Auto for relevant formats and are detected directly from the file itself, so you only need to touch them in the rare case detection gets something wrong, an unusual delimiter or a legacy encoding, for example. This makes the tool equally useful for data analysts working with irregular exports, developers automating a recurring pipeline step, e-commerce teams distributing catalog data by category, and anyone else who regularly runs into the practical limits of opening a large data file directly in a spreadsheet program.
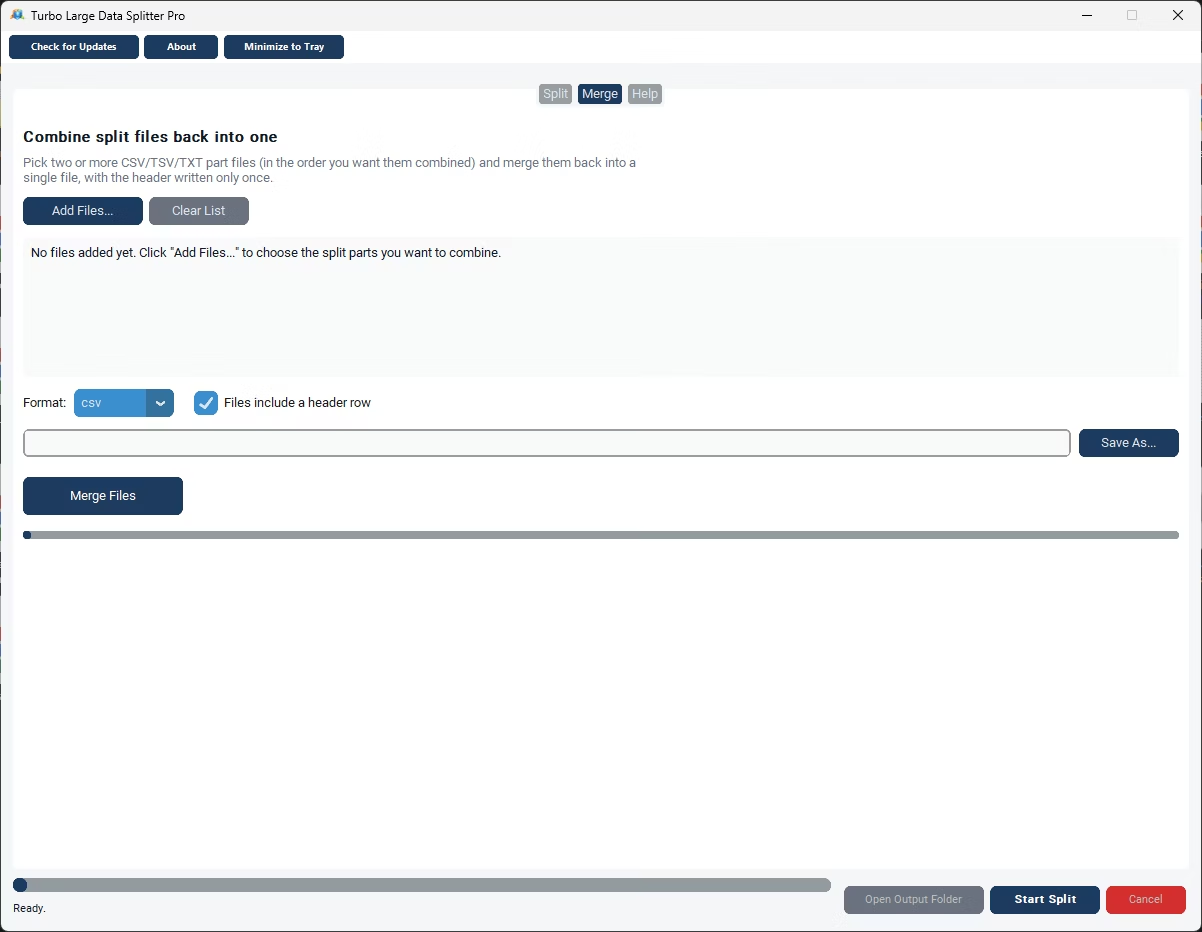
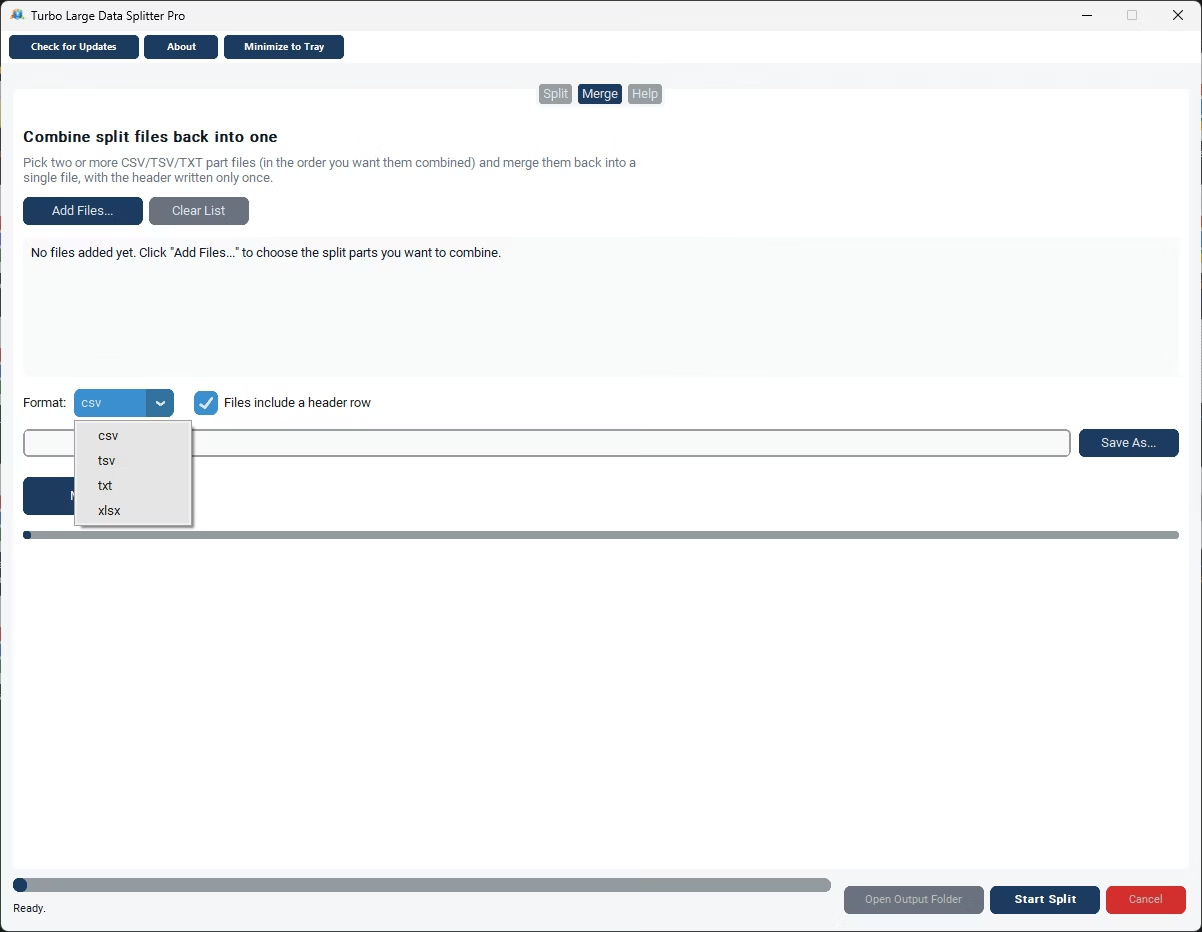
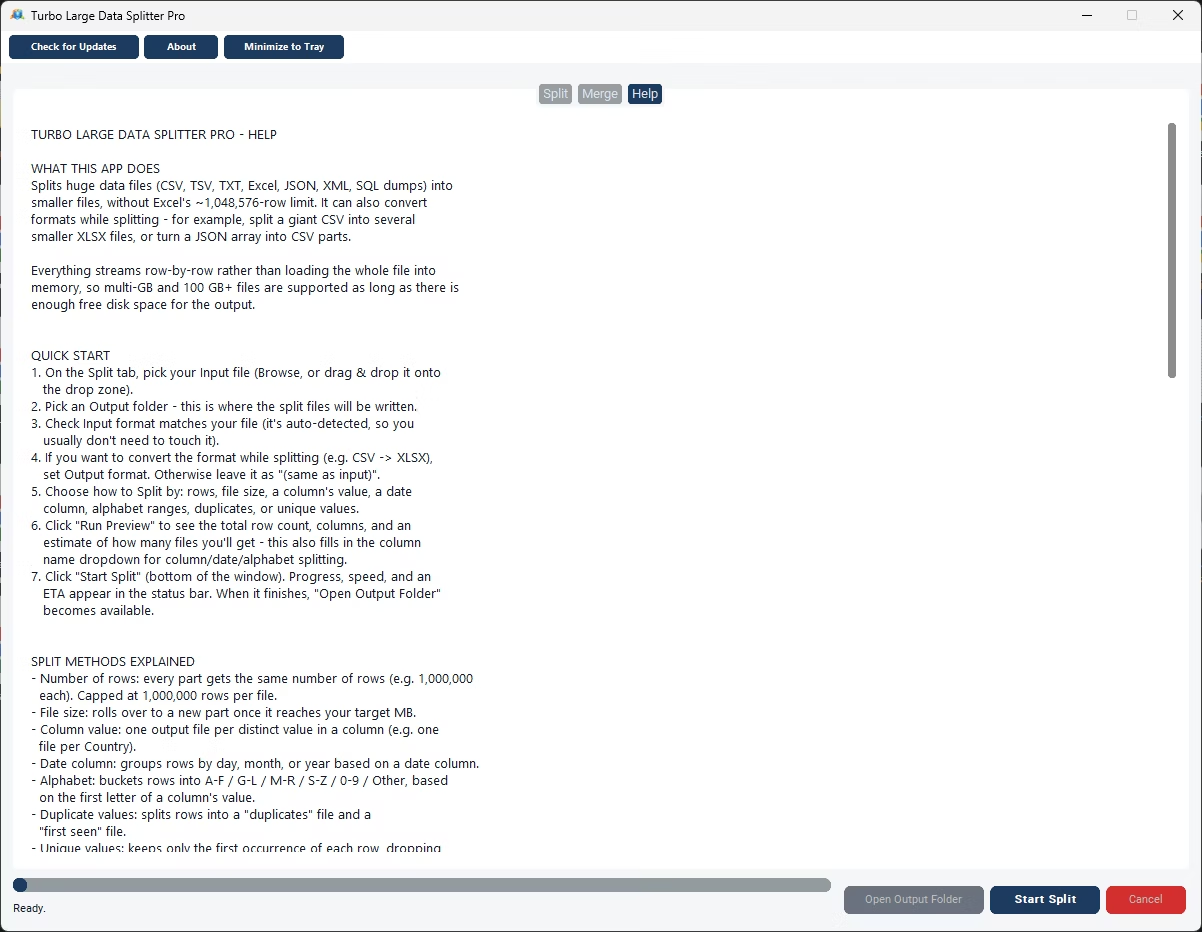
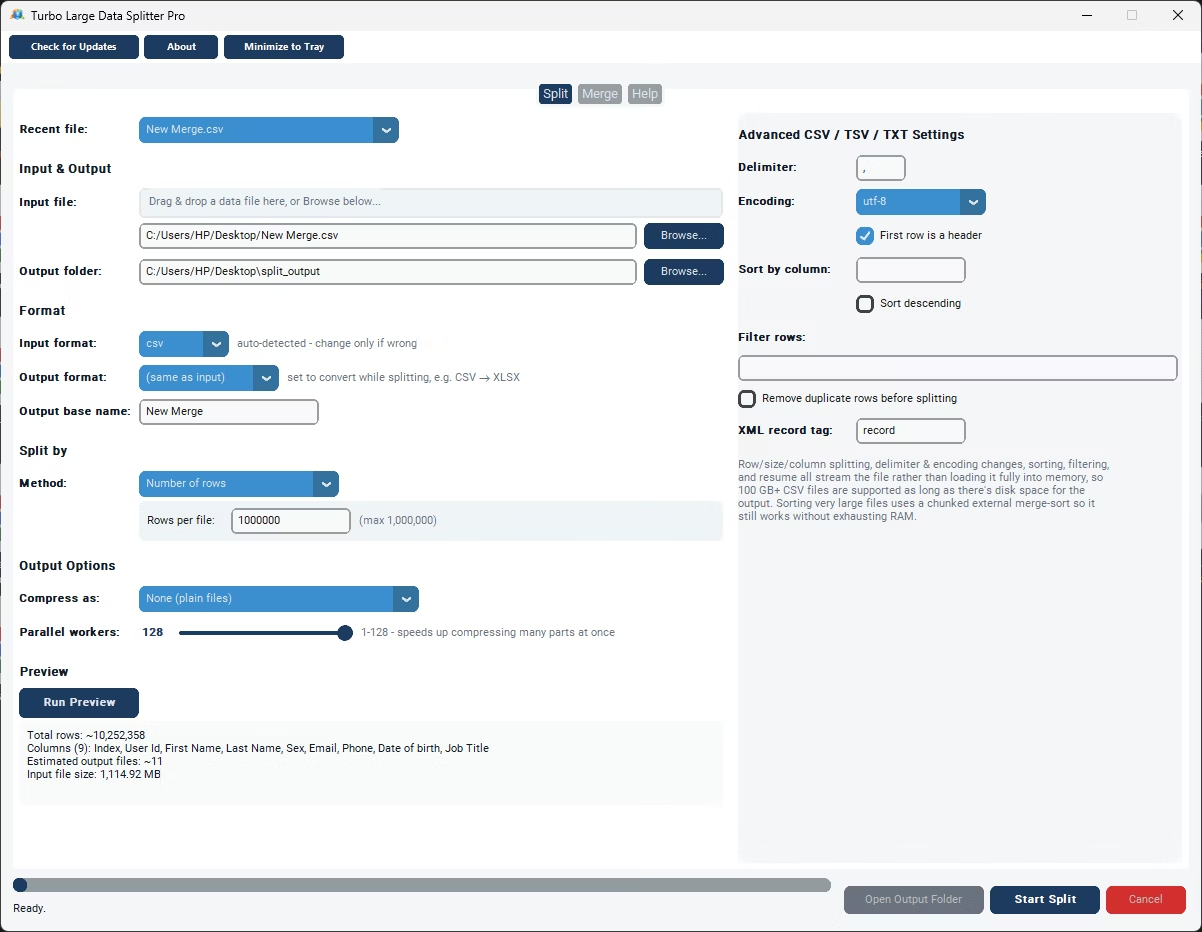
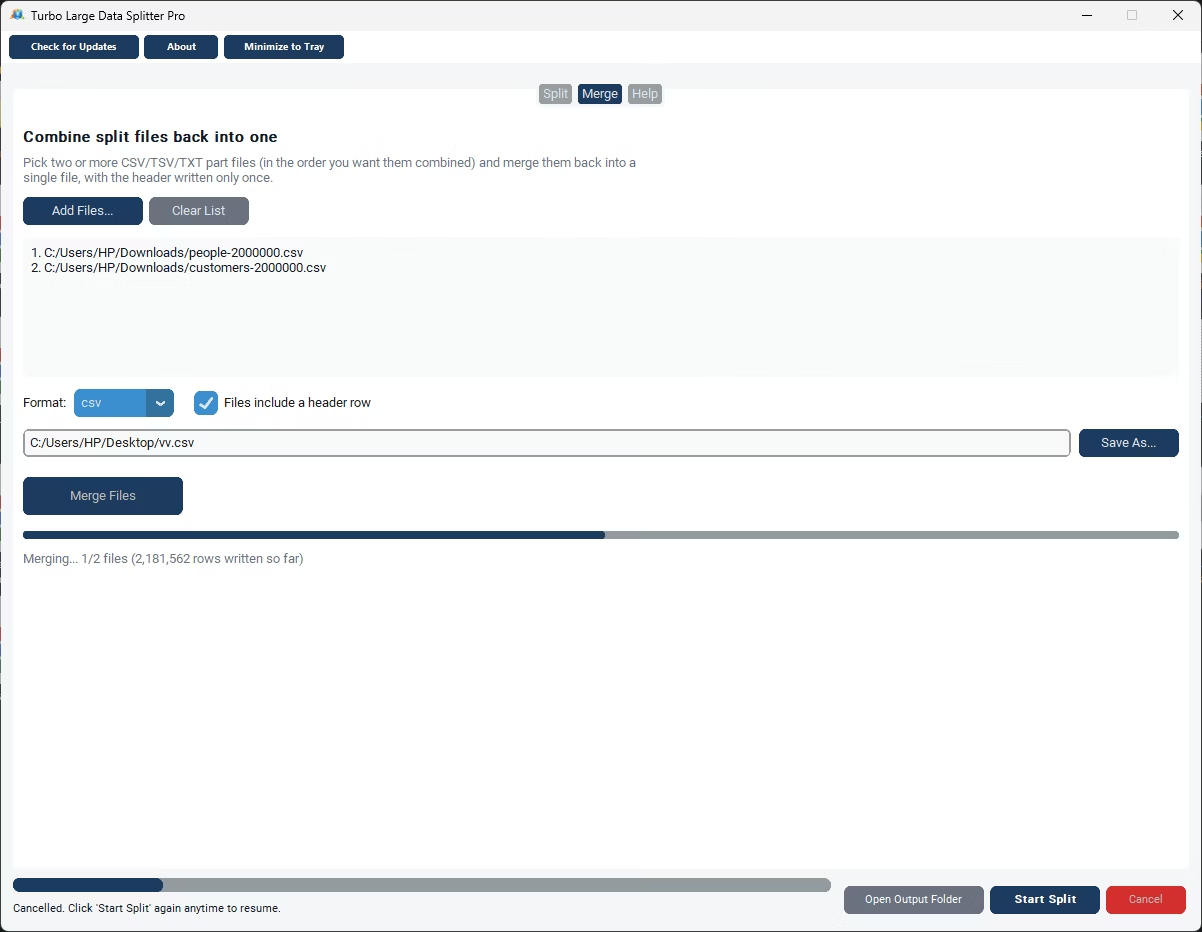
- Install Turbo Large Data Splitter on your Windows PC.
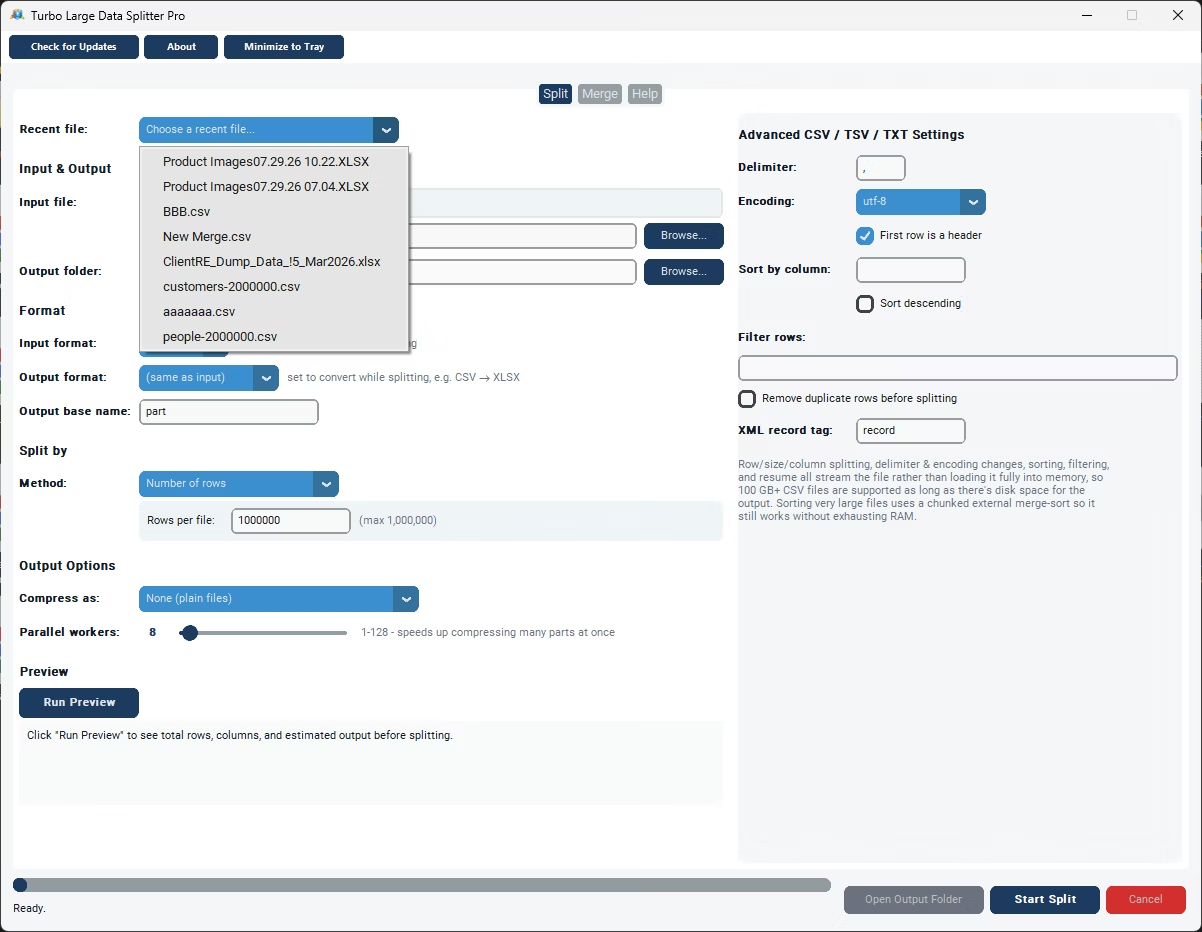
- Browse to or drag and drop your extremely large data file.
- Choose your output folder with enough free disk space.
- Select the split method that matches your need.
- Run Preview to confirm the setup.
- Click Start Split and monitor speed and ETA.
- Resume from checkpoint if the job is interrupted.
- Open the output folder once the split completes.
- Adjust the parallel worker slider if compressing many output parts.
- Check the status bar for the final row count and file count summary.
- Streaming engine handles extremely large files without memory limits
- Supports multi-GB and 100 GB+ files across most formats
- Seven split methods for different massive-file scenarios
- Live speed and ETA for realistic progress tracking on long jobs
- Checkpoint-based resume critical for hours-long jobs
- No upload step, avoiding a slow start for massive files
- Runs fully offline with no upload of large data volumes
- One-time purchase for Windows, with Gumroad license activation
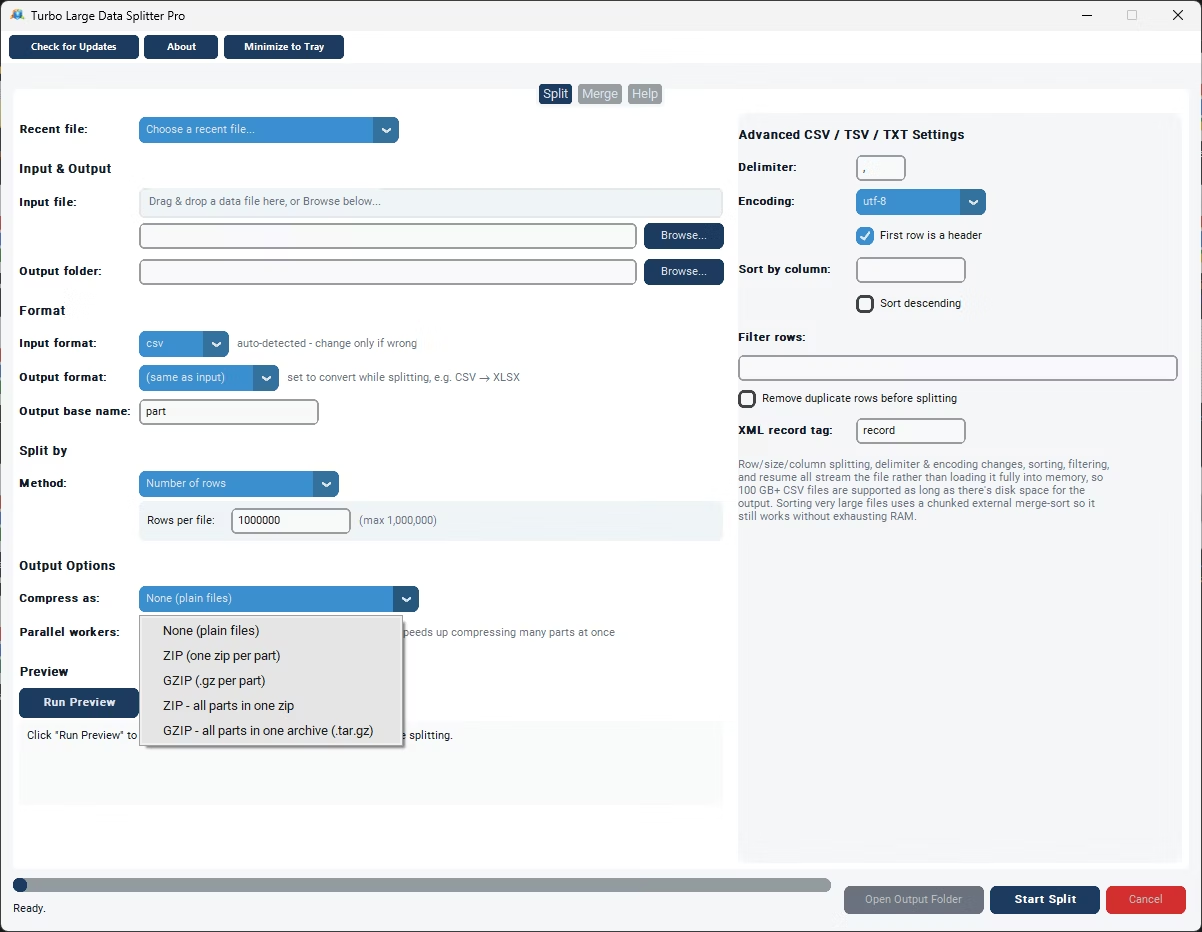
- Compression options: uncompressed, per-part ZIP/gzip, or a single bundled archive
- Works with files on local drives, external drives, and network shares
What's the largest file this tool can genuinely process?
The practical limit is your available disk space rather than a fixed cap for most formats; 100 GB+ files are supported as long as there's enough free space for the output.
How long does processing a file this large typically take?
It depends on file size and your PC's resources, but the live status bar shows speed and an ETA so you can track actual progress throughout what can be an hours-long job.
Why does checkpoint resume matter so much at this scale?
Jobs processing extremely large files can run for a significant amount of time, so resuming from a checkpoint rather than restarting saves substantial reprocessing time if a job is interrupted.
Does file format affect how large a file can be processed?
Most formats stream without memory limits; legacy .xls is the exception, loaded whole into memory, though it caps at 65,536 rows anyway so this rarely becomes a practical constraint.
Does this work on both Windows 10 and Windows 11?
Yes, Turbo Large Data Splitter is built and tested for both Windows 10 and Windows 11.
Is my data safe when using this tool?
Yes, all processing happens locally on your PC; no files are ever uploaded, so proprietary or sensitive data stays fully under your control.
Can I compress the split output files?
Yes, you can leave parts uncompressed, zip or gzip each part individually, or bundle everything into a single ZIP or gzip archive, sped up by a parallel worker slider.
Can I use this on files stored on an external or network drive?
Yes, data files on local drives, external drives, or mapped network shares all work the same as any local file.
Can I cancel a split job partway through if I need to?
Yes, cancelling saves a checkpoint file in the output folder, so you can resume the job later exactly where it left off instead of starting over.
Is there a trial version available before buying?
Check the product page on turbo-soft.com for current trial availability and details.
Ready to process your extremely large data files, fully offline?