Split, Merge, and Profile Large CSV Files Without Excel Limits
Turbo CSV Splitter is a focused Windows desktop tool for working with CSV files that have grown too big to handle comfortably in a spreadsheet. Instead of trying to be an all-purpose data suite, it does one family of jobs extremely well: breaking a huge CSV into smaller, well-formed CSV files, stitching parts back together, and inspecting a file's columns for data-quality problems. Everything runs locally on your PC, so your data never leaves your machine and there is no upload, account, or subscription in the way. As a dedicated csv file splitter, it is built to handle files a spreadsheet simply refuses to open.
Why This Tool Exists
Spreadsheets and many everyday tools quietly cap out at Excel's 1,048,576-row limit, and even well below that, a multi-gigabyte CSV can freeze a machine or refuse to open at all. Exporting a large table from a database, an analytics platform, or a CRM often produces a single enormous file that is awkward to email, import, review, or load into another system. Turbo CSV Splitter exists to make that file manageable again - cutting it into parts sized for whatever comes next, whether that is opening cleanly in Excel, importing under a size cap, or feeding a machine-learning pipeline.
What Problems It Solves
- CSV files too large to open in Excel, Google Sheets, or a text editor.
- Exports that exceed an import size or row limit in another application.
- The need to break one file into logical pieces - per region, per date, per category - instead of arbitrary chunks.
- Reassembling previously split parts into a single clean CSV with one header.
- Catching malformed, ragged, or inconsistent data before it causes an import to fail downstream.
- Doing all of the above on sensitive data that cannot be uploaded to a web service.
Who Should Use It
Anyone who regularly receives or produces large CSV exports: data analysts and engineers preparing datasets, finance and accounting teams handling transaction dumps, marketers and CRM administrators segmenting contact lists, researchers chunking data for processing, and IT and operations staff moving data between systems that impose size limits. If your work involves CSV files that are inconveniently large, this is the tool built for exactly that.
Supported File Format
Turbo CSV Splitter is built to do one job well: split large CSV files into smaller, well-formed CSV files. Delimiters and encodings are detected automatically, so you can drop in a file and start splitting right away.
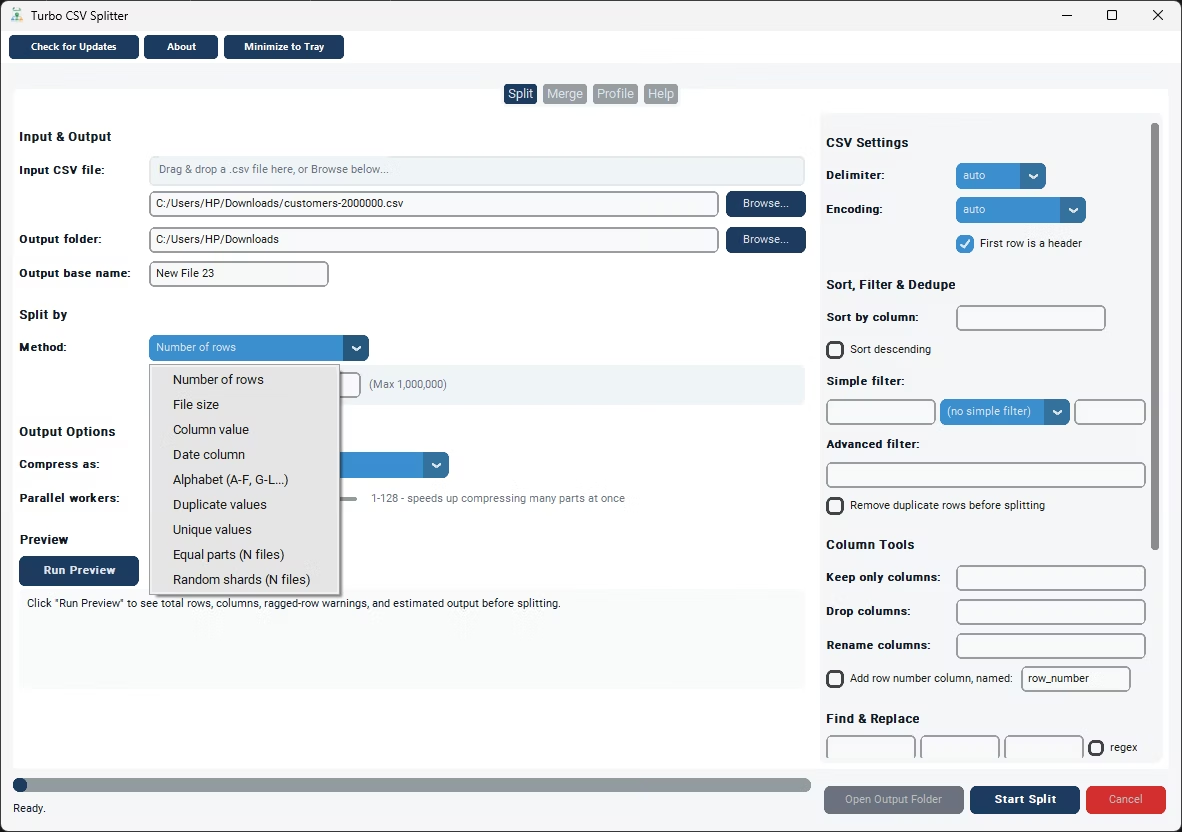
9 Ways to Split a CSV File
| Number of Rows | → | Every output file gets the same row count, up to 1,000,000 rows per file. |
| File Size | → | Rolls over to a new part once it reaches your target size in MB. |
| Column Value | → | Writes one output file per distinct value found in a chosen column. |
| Date Column | → | Groups rows by day, month, or year based on a date column, auto-parsing common date formats. |
| Alphabet | → | Buckets rows into A-F / G-L / M-R / S-Z / 0-9 / Other, based on the first letter of a column's value. |
| Duplicate Values | → | Splits rows into a "duplicates" file and a "first seen" file. |
| Unique Values | → | Keeps only the first occurrence of each row, dropping every later duplicate. |
| Equal Parts (N Files) | → | Splits the file into exactly N roughly-equal files (a quick row count runs first). |
| Random Shards (N Files) | → | Randomly assigns every row to one of N output files - ideal for train/test/validation splits. A seed makes the assignment reproducible, even on resume. |
Every Split Method Explained
Choosing the right split method is the difference between arbitrary chunks and output that maps directly to how you actually work. Here is what each of the nine methods does, when to reach for it, and a concrete example.
Split by Number of Rows
The most common method: every output file gets the same number of data rows, up to a ceiling of 1,000,000 rows per file. Enter, say, 500,000 and a five-million-row export becomes ten tidy files. This is the go-to when you simply need pieces that open in Excel without hitting its row ceiling, or that stay under an import limit. The header is repeated at the top of every part, so each file is independently valid.
Split by File Size
Instead of counting rows, this method rolls over to a new part as soon as the current one reaches your target size in megabytes. Use it when the constraint is a size cap rather than a row count - for example, an upload portal that rejects files over 100 MB, or an email attachment limit. Because rows vary in width, size-based parts hold different row counts but all stay near your chosen size.
Split by Column Value
Writes one output file per distinct value in a column you pick. Point it at a Region column and you get one file per region; point it at Customer and you get one file per customer. This turns a single blended export into a set of ready-to-distribute files, each containing only the rows for one group - ideal for handing regional data to regional teams or splitting a master list by category.
Split by Date Column
Groups rows by day, month, or year based on a date column, parsing common date formats automatically. A year of transactions can become twelve monthly files, or 365 daily files, in one pass. This is the natural choice for time-series data, monthly reporting, or archiving records into period-based files without writing a single formula.
Split by Alphabet
Buckets rows into A-F, G-L, M-R, S-Z, 0-9, and Other based on the first letter of a chosen column's value. It is a quick way to break a large directory of names, products, or codes into predictable alphabetical sections - handy for reference lists and lookups where alphabetical grouping matches how people search.
Split by Duplicate Values
Separates rows into a "duplicates" file and a "first seen" file, so you can isolate repeated records for review rather than deleting them outright. This is useful when duplicates might be meaningful - repeat orders, resubmissions, or data-entry errors you want to inspect before deciding what to keep.
Split by Unique Values
Keeps only the first occurrence of each row and drops every later duplicate, producing a single de-duplicated file. Reach for this when you know duplicates are noise and simply want one clean copy of each record.
Split into Equal Parts
Divides the file into exactly N roughly-equal files - a quick row count runs first so the tool knows how many rows belong in each part, with the last file possibly a little smaller. Choose this when you want a specific number of pieces (say, four files to hand to four people) rather than a specific size or row count.
Split into Random Shards
Randomly assigns every row to one of N output files, which is exactly what you want for machine-learning train/test/validation splits. A fixed random seed makes the assignment fully reproducible - the same seed always produces the same split, even if you cancel and resume the job later.
How It Works: A Step-by-Step Split
The workflow is deliberately linear, so even a first-time user can go from a giant file to clean output in a couple of minutes.
1. Load Your CSV
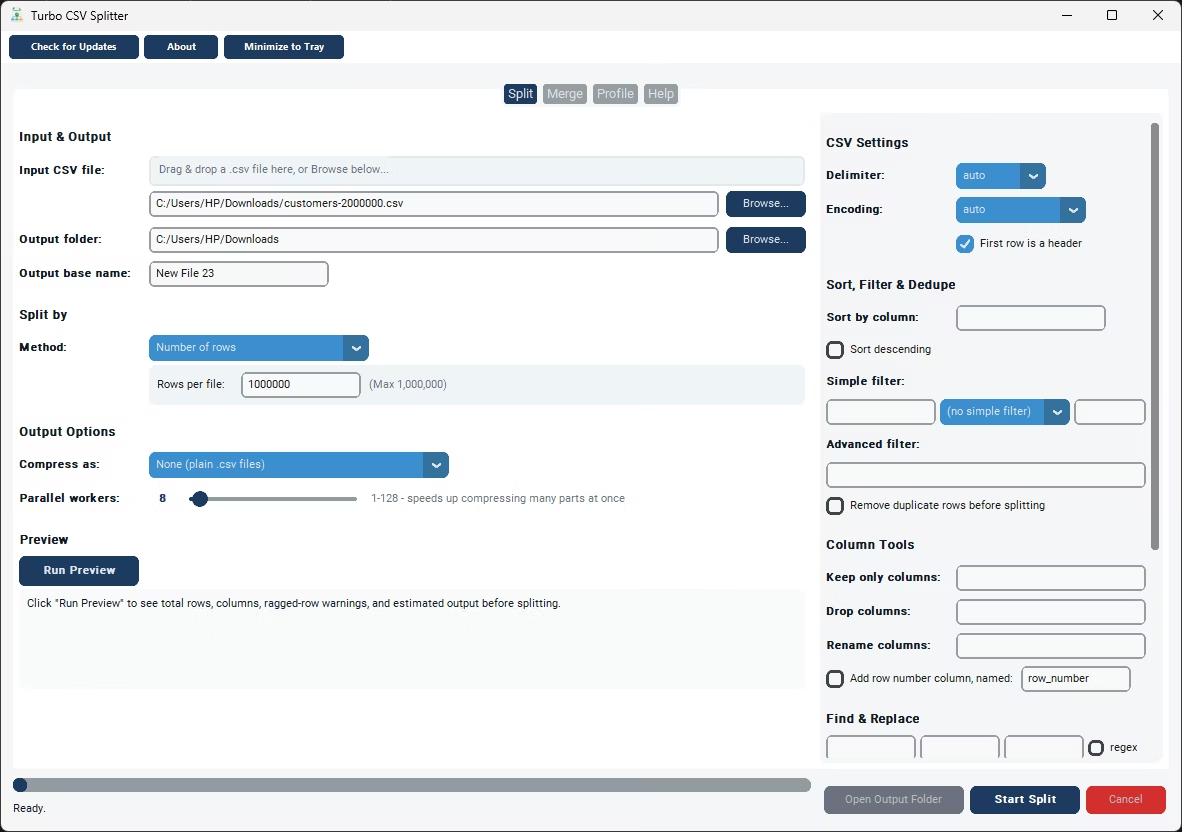
On the Split tab, browse to your input CSV or drag and drop it onto the drop zone. There is no format picker, because the app works with CSV only - nothing to choose, nothing to misconfigure.
2. Set the Output Folder
Choose where the split files will be written. Every part, plus any archive or checkpoint file, lands in this folder.
3. Confirm Delimiter and Encoding
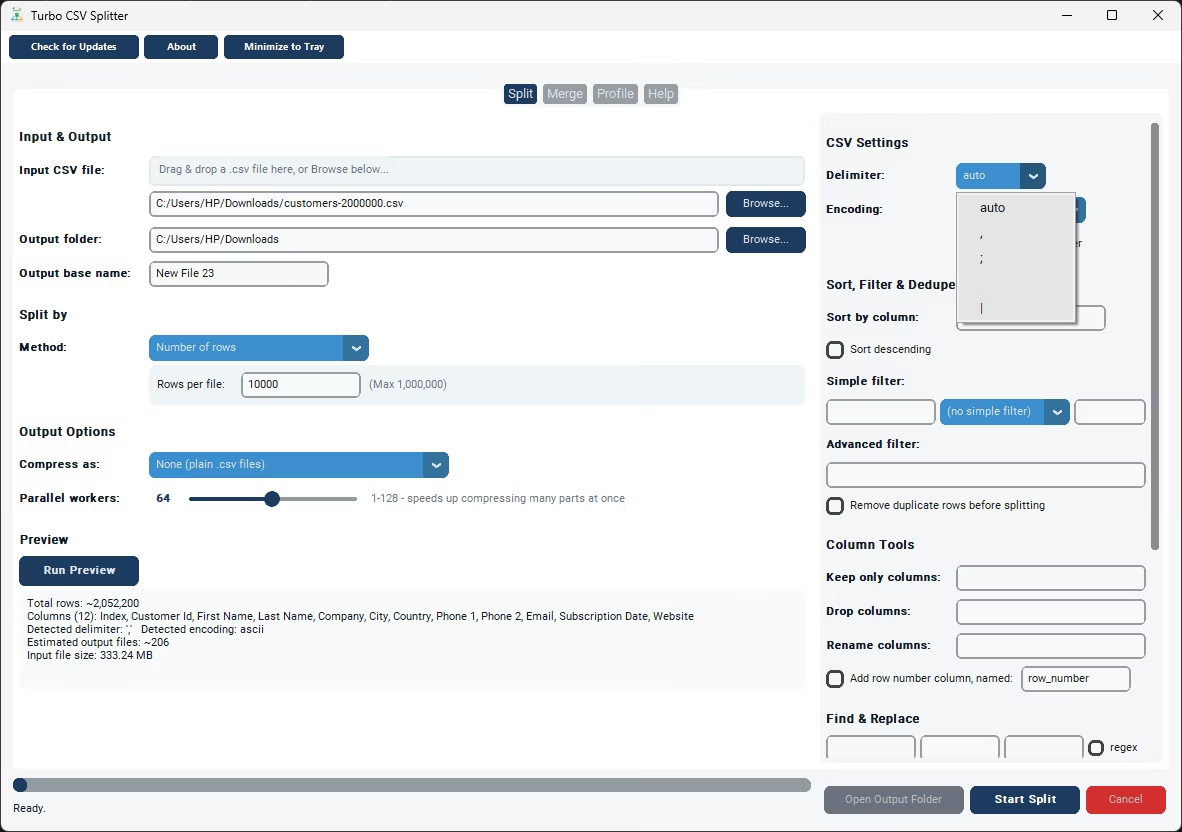
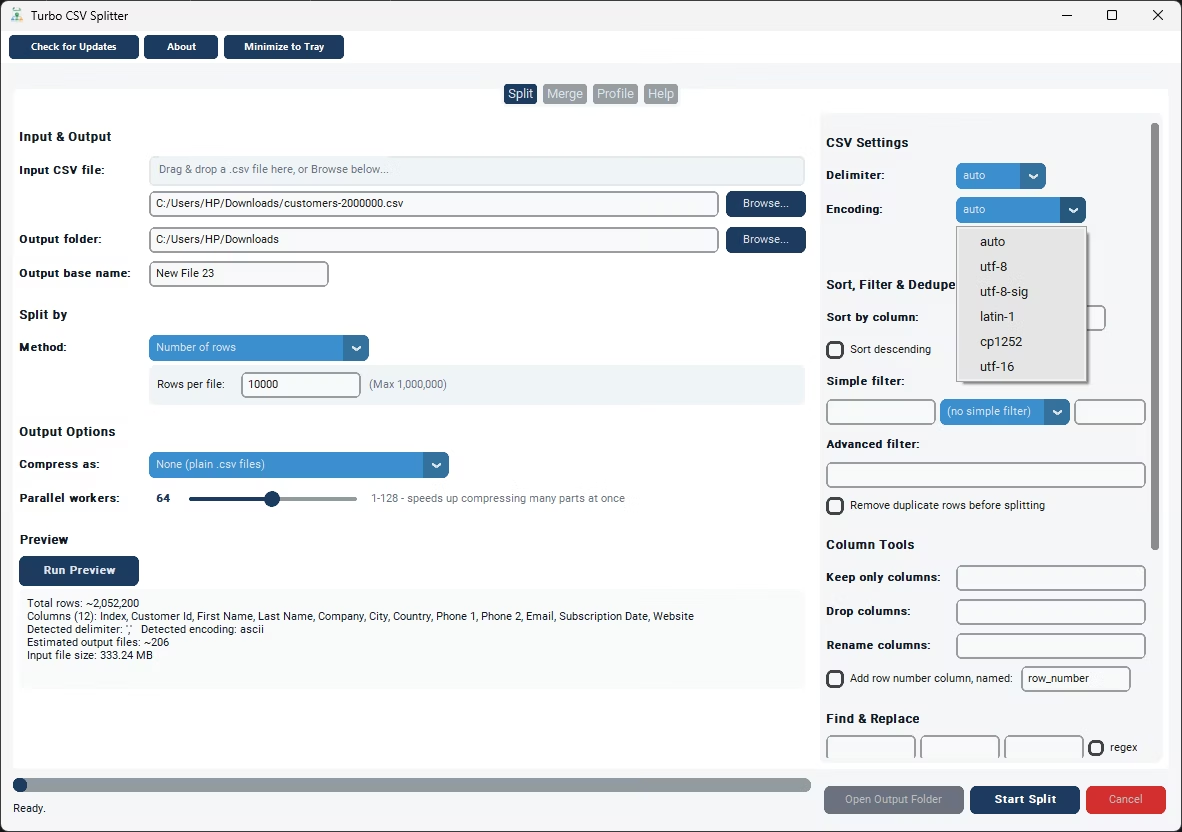
Both default to Auto and are detected from the file itself. You only touch them in the rare case detection gets it wrong, for example an unusual delimiter or a legacy encoding.
4. Choose How to Split
Pick one of the nine split methods and fill in its single setting - rows per file, target MB, the column to split on, the number of parts, and so on.
5. Run Preview
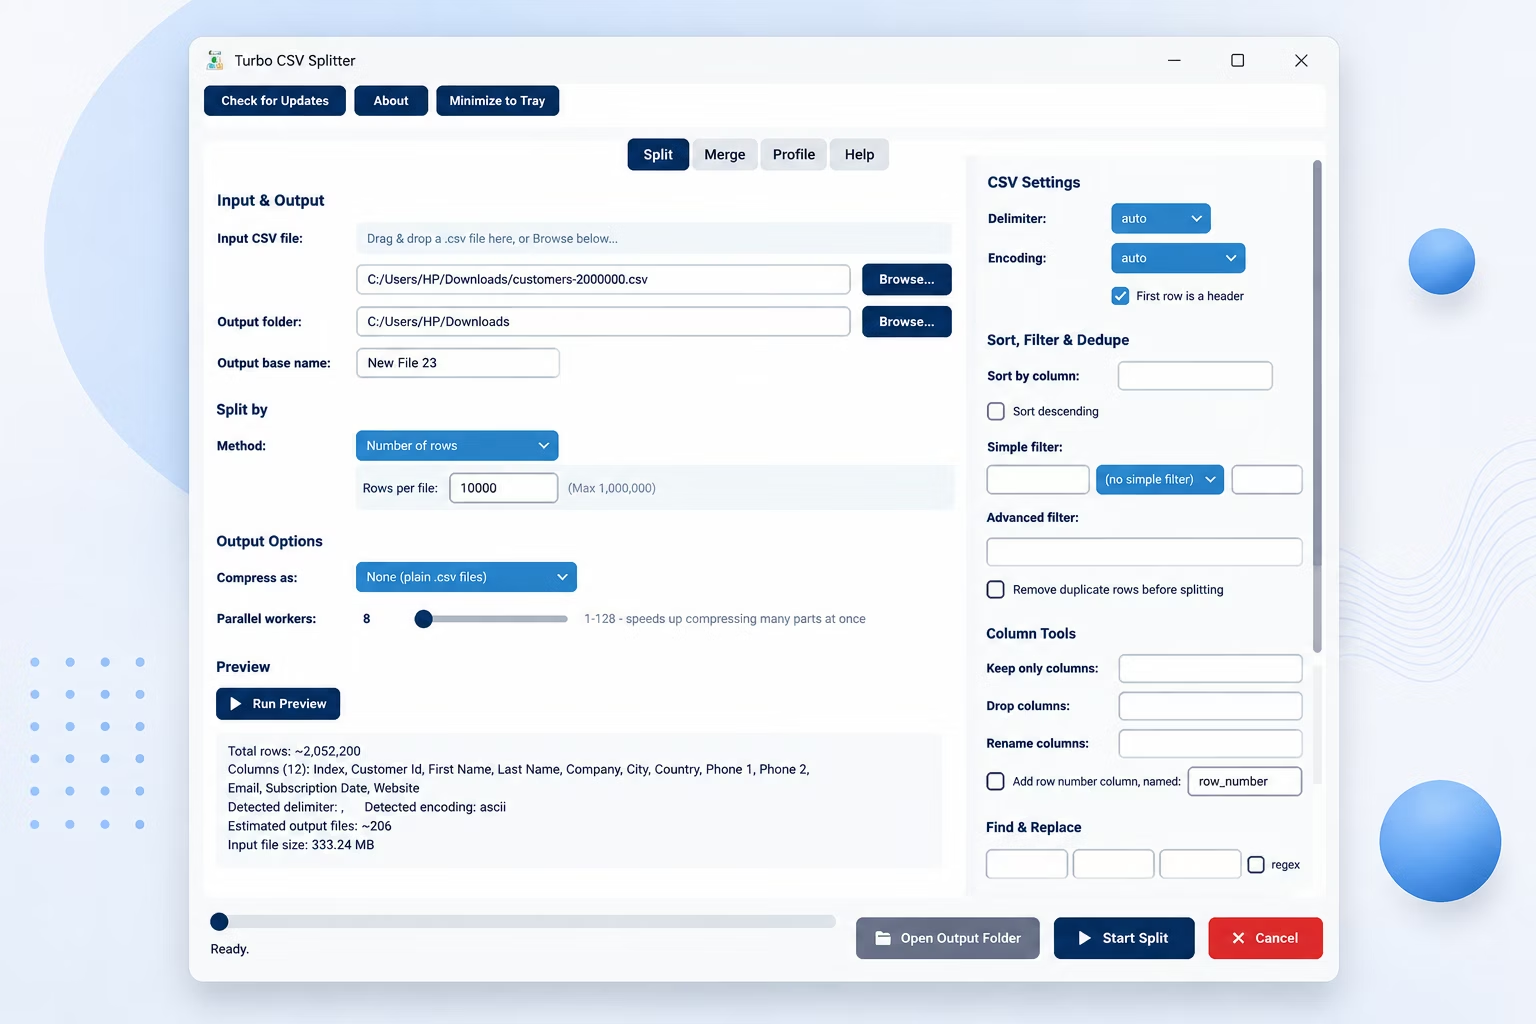
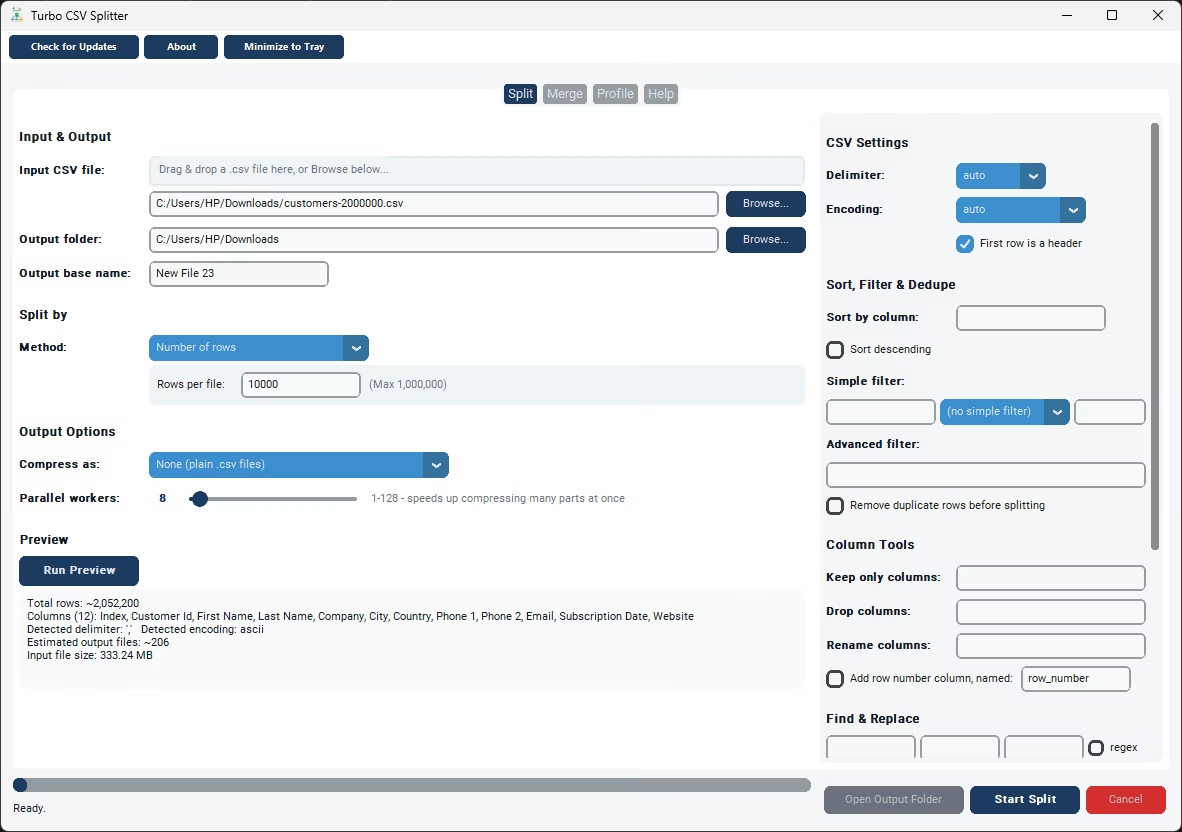
Preview reports the total row count, the detected columns, any ragged-row warnings, sample rows, and an estimate of how many output files you will get - a safety check before committing.
6. Start Split
Click Start Split and watch the status bar show progress, live speed in rows per second, and an ETA. When it finishes, Open Output Folder takes you straight to the results.
The Four Tabs: Split, Merge, Profile, Help
The app is organized into four clearly labelled tabs, presented in a clean light theme. Each tab is self-contained, so you always know which job you are doing.
Split Tab
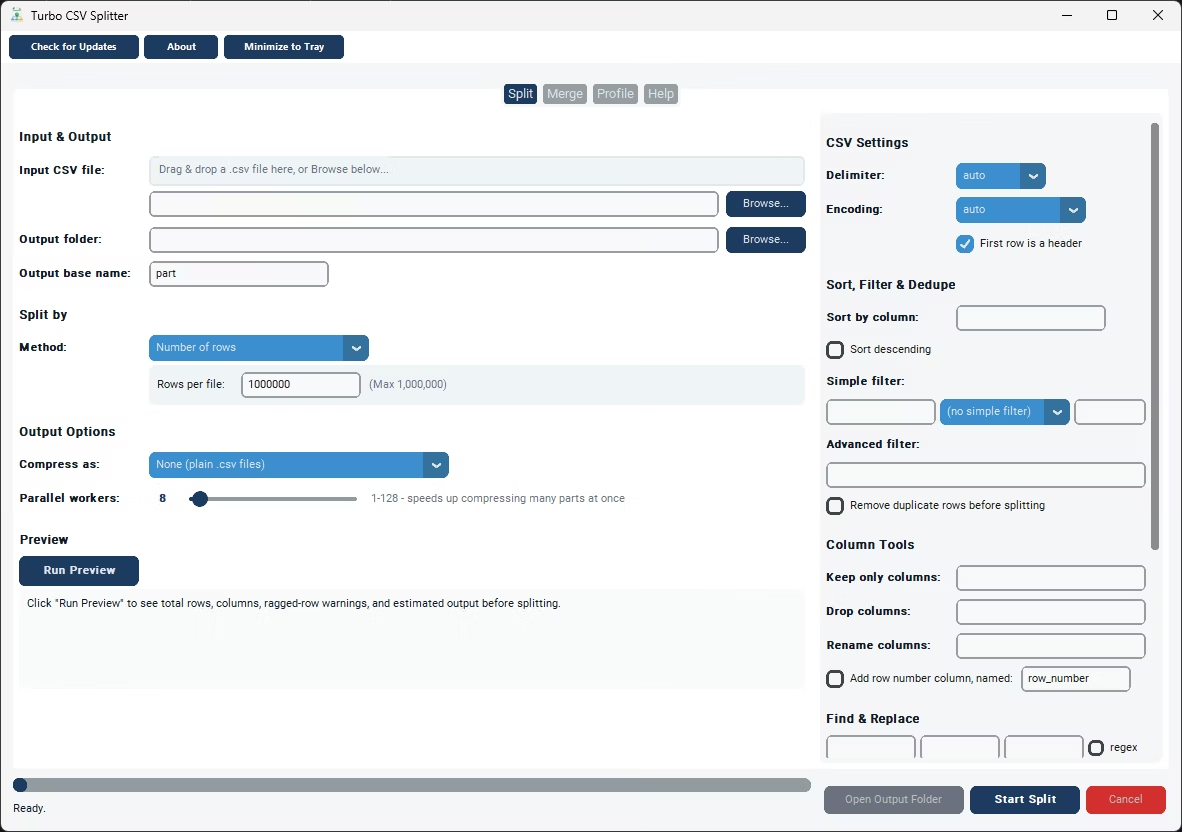
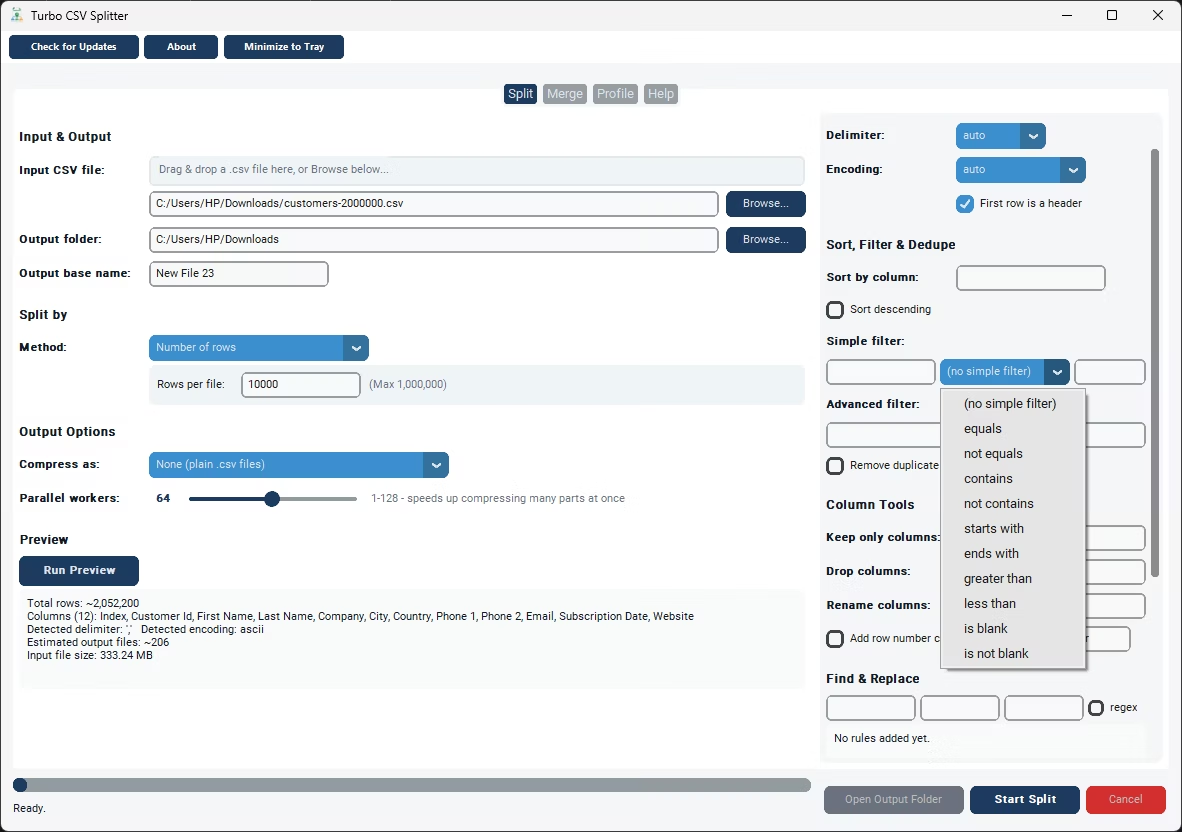
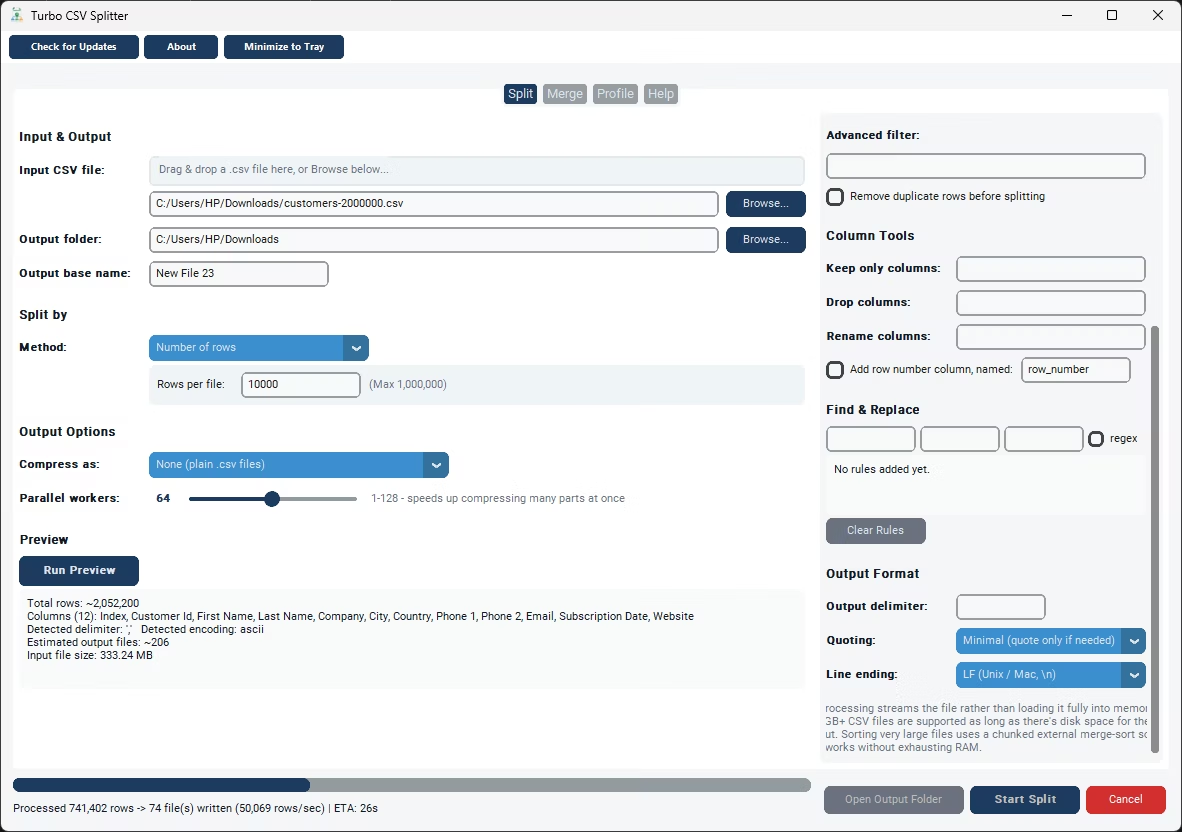
The heart of the app. Input file, output folder, delimiter and encoding, the nine split methods, and the full set of column tools, filters, sort, dedupe, and output settings all live here, alongside Preview and Start Split.
Merge Tab
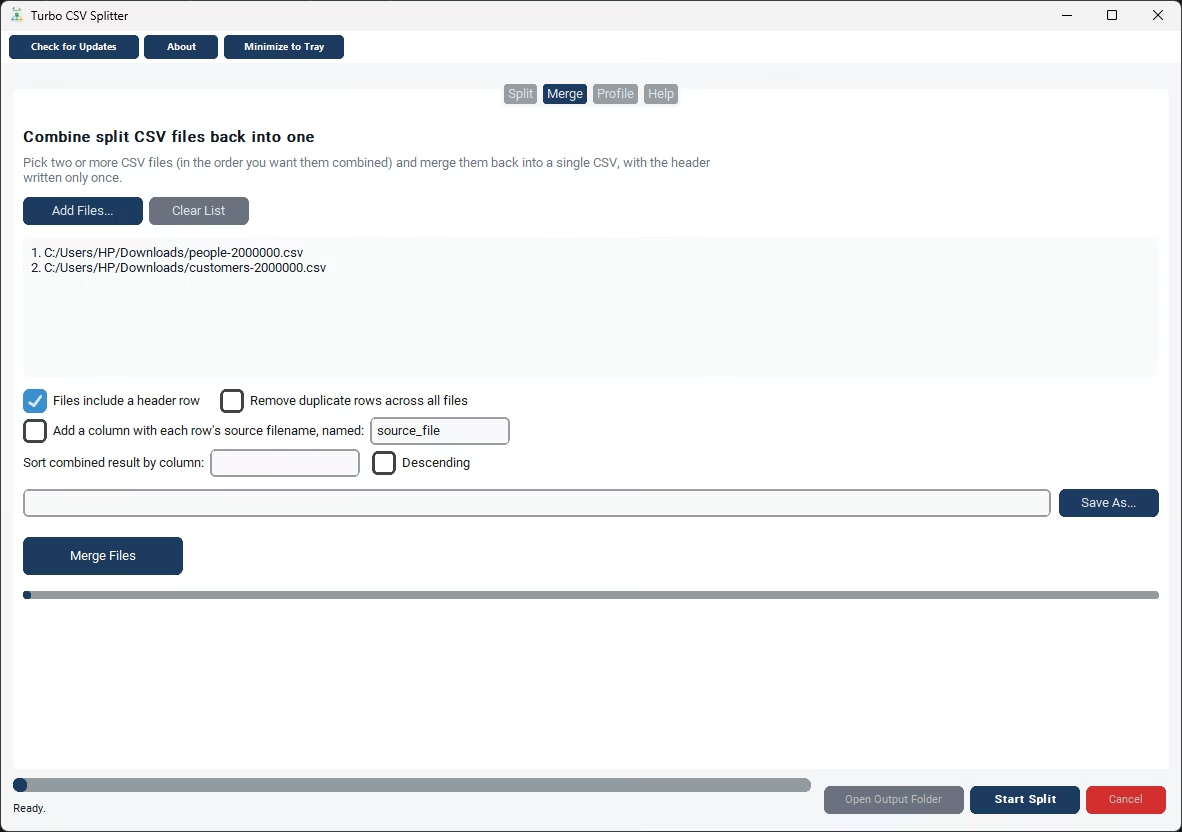
Combine two or more CSV files - including parts you split earlier - back into one CSV, writing the header a single time. You can tag each row with its source filename, drop duplicate rows across all files, and sort the merged result by a column.
Profile Tab
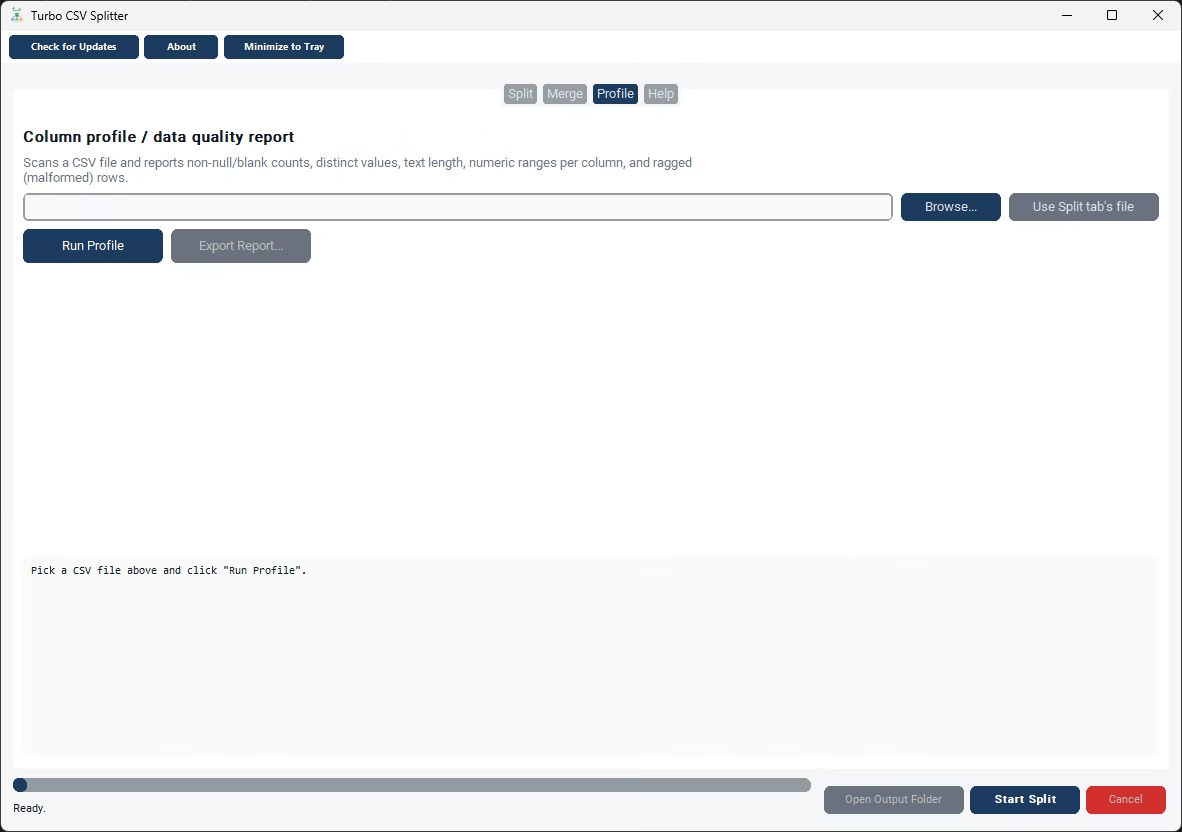
A data-quality inspector. Point it at a CSV and it reports per-column non-null and blank counts, distinct-value counts, min and max text length, and numeric min, max, and mean, while flagging ragged rows. The report exports to a text file.
Help Tab
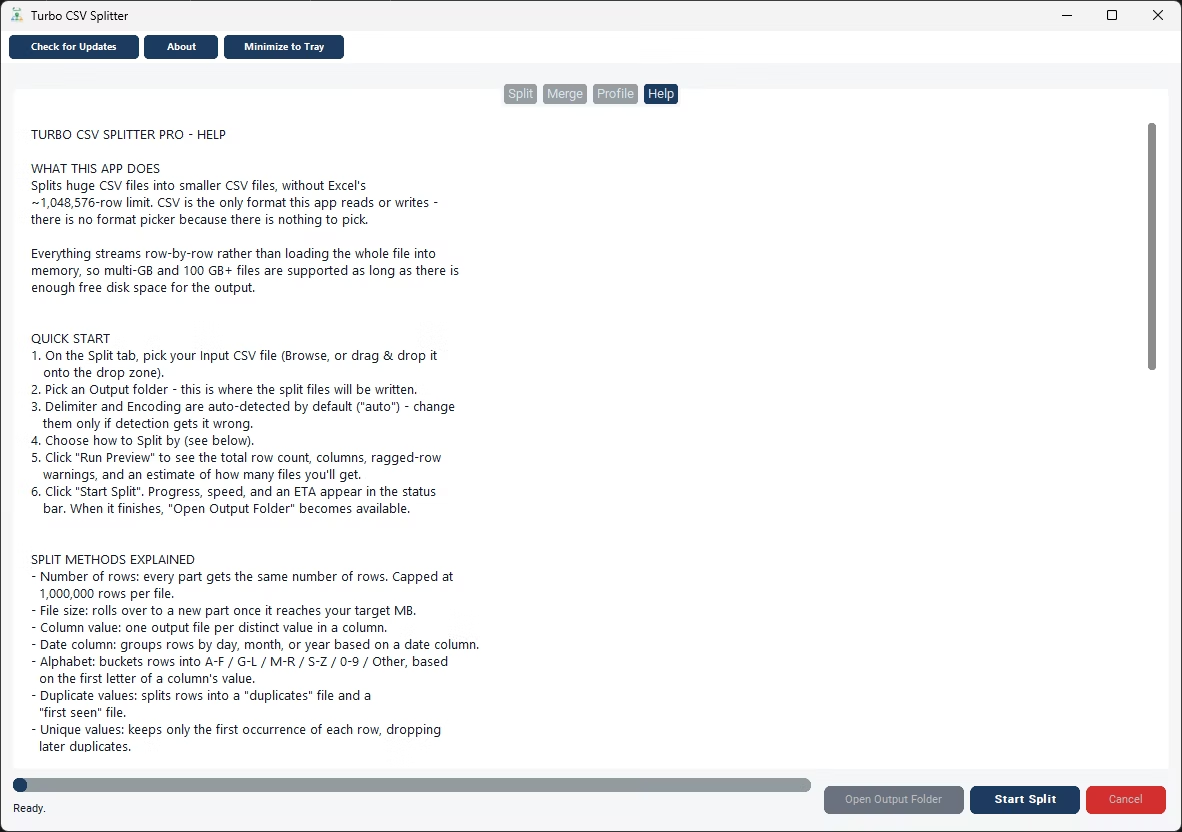
Built-in documentation covering the quick-start flow, every split method, the column and filtering tools, output settings, and how resume works - so guidance is always a click away inside the app.
Key Features
▶ Split Tab
Pick your input CSV (Browse, or drag-and-drop onto the drop zone), choose an output folder, select a split method, and click Start Split. Delimiter and encoding default to Auto. Progress, live speed in rows/sec, and an ETA appear in the status bar as the job runs.
▶ Merge Tab
Combine two or more CSV files - including previously split parts - back into a single CSV, with the header written only once. Optionally tag each row with its source filename, remove duplicate rows across all files, and sort the combined result by a column.
▶ Profile Tab
Scans a CSV and reports, per column: non-null/blank counts, distinct value counts, min/max text length, and (for numeric-looking columns) the min, max, and mean. Flags ragged rows with a different field count than the header. Export the report to a text file.
Free CSV Splitter Download
The csv splitter download installs in minutes on Windows 10 or 11 and runs fully offline afterward - no subscription, no cloud upload, and no ongoing account needed once the csv splitter download and one-time license activation are done.
No Excel Row Limit
Split files with tens of millions of rows into parts that open cleanly in Excel or any spreadsheet tool, without ever hitting the 1,048,576-row ceiling.
Streaming Engine for Huge Files
Rows are read and written one at a time rather than loaded into memory, so multi-GB and 100 GB+ CSV files are supported as long as there's free disk space for the output.
Auto-Detect Delimiter & Encoding
Samples the file to detect comma, semicolon, tab, or pipe delimiters, and encodings including UTF-8, UTF-8-SIG, UTF-16, CP1252, and Latin-1. Override manually if needed.
Cancel & Resume From Checkpoint
Cancel a running job at any time - a checkpoint file is saved in the output folder. Click Start Split again with the same file and settings to resume exactly where you left off instead of starting over.
Run Preview Before You Split
Run Preview to see the total row count, detected columns, ragged-row warnings, sample rows, and an estimate of how many output files you'll get - before committing to the full job.
Column Data Quality Profiling
Spot data-quality issues before you split or merge: null/blank counts, distinct-value counts, text length ranges, and numeric min/max/mean per column, plus a ragged-row count.
1-128 Parallel Workers
A worker slider from 1 to 128 speeds up compressing many output parts at once, scaling to match your CPU.
Drag & Drop Support
Drop a CSV file straight onto the app window instead of browsing for it, for a faster start to every split job.
Minimize to System Tray
Send the app to the system tray while a large split or merge job runs in the background, and reopen it from the tray icon when it's done.
Column Tools & Data Transformation
- Keep Only These Columns / Drop These Columns - comma-separated column names; if "Keep only" is filled in, "Drop" is ignored.
- Rename Columns - pairs like
old:new, old2:new2rename headers in the output without changing which data goes where. - Add Row Number Column - prepends a running row-number column, starting at 1, to every output file.
- Find & Replace - add one or more rules, optionally limited to a single column and with optional regex, applied to every row before it's written.
- Output Delimiter - leave blank to match the input delimiter, or set a different one to convert on the way out (e.g. comma-in, semicolon-out).
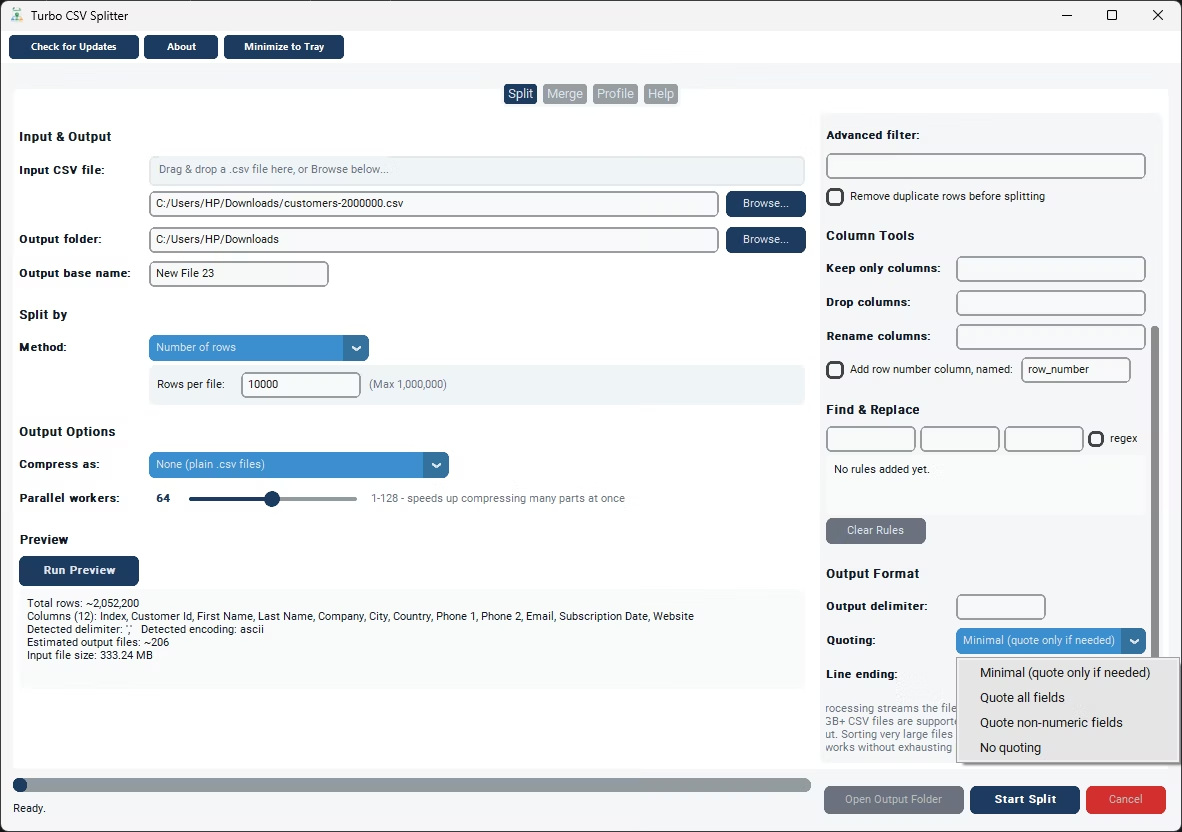
- Output Quoting - minimal, quote all fields, quote non-numeric fields, or no quoting.
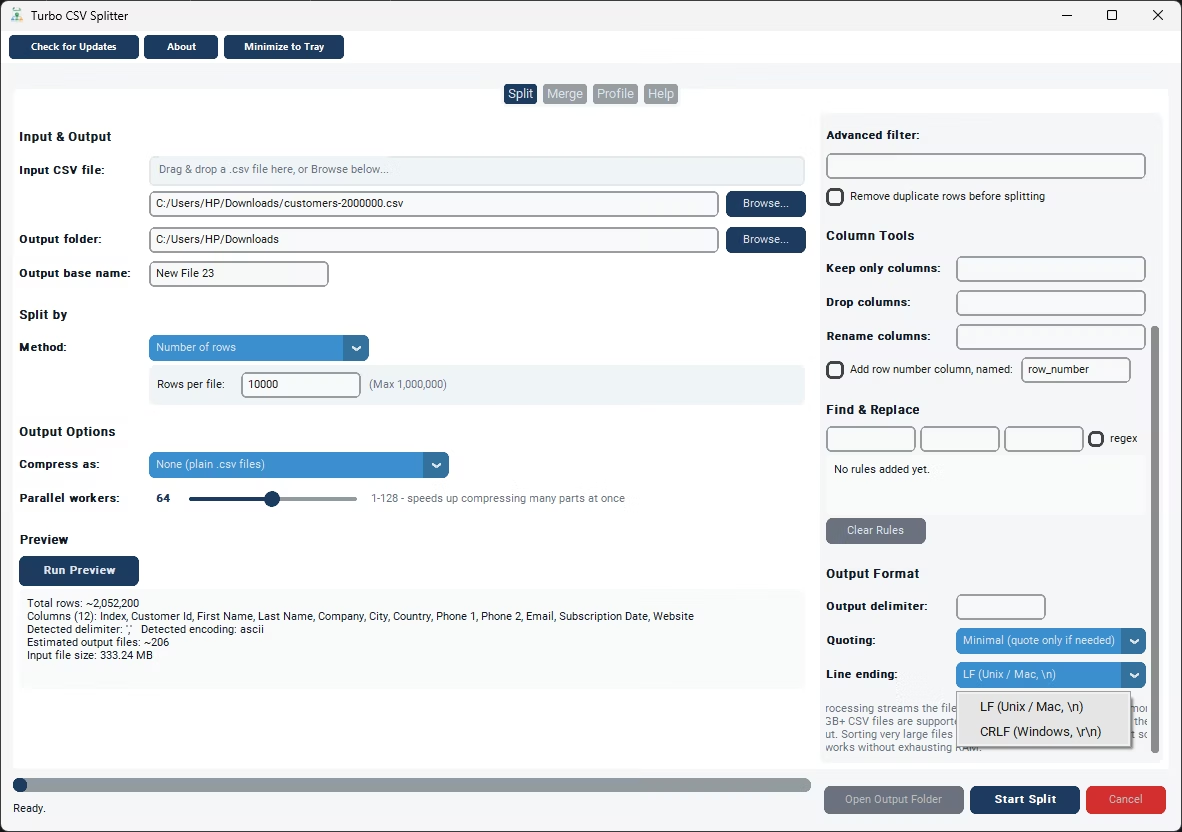
- Line Ending - choose LF (Unix/Mac) or CRLF (Windows).
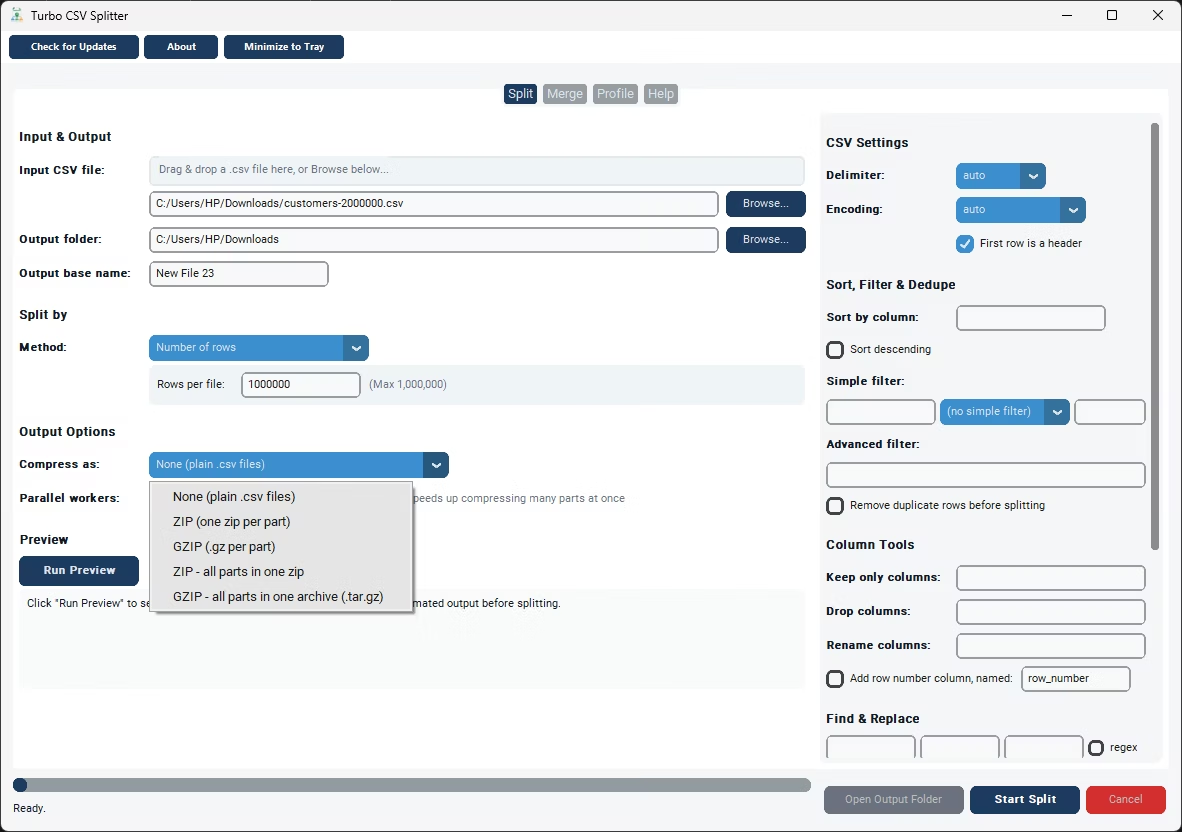
- Compression - leave parts uncompressed, zip or gzip each part individually, or bundle every part into one ZIP or .tar.gz archive.
Output Format Control
Splitting is only half the job - the parts also need to match whatever reads them next. Turbo CSV Splitter gives you precise control over how the output is written, so a single run can split and reformat at the same time.
Output Delimiter
Leave it blank to keep the input delimiter, or set a different character to convert on the way out - comma in, semicolon or tab out - without a separate conversion step.
Quoting Style
Four modes: quote minimally (only when needed), quote all fields, quote non-numeric fields, or no quoting. Match the exact convention the destination system expects.
Line Ending
Choose LF for Unix and macOS pipelines or CRLF for Windows tools, so line breaks are correct wherever the files are consumed.
Compression
Write plain CSV, zip or gzip each part on its own, or bundle every part into one ZIP or gzip archive - useful for keeping a split job together as a single download.
Custom Base Name
Set the base filename used for output parts, so the resulting files follow your own naming convention rather than a generic default.
Add Row Number Column
Prepend a running row-number column starting at 1 to every output file, giving each row a stable identifier that survives the split.
Filtering, Sorting & Deduplication
Simple Filter
Pick a column, an operator (equals, contains, starts with, greater than, is blank, and more), and a value - no coding needed.
Advanced Filter
Write a Python expression using row as the row dictionary, e.g. row["Country"] == "USA", applied in addition to the simple filter.
Sort by Column
Optional chunked external merge-sort so even huge files sort correctly without exhausting RAM, ascending or descending.
Remove Duplicate Rows
Drops exact duplicate rows, compared across all columns, before the file is split or merged.
Who Uses Turbo CSV Splitter and How
Large CSV files turn up in almost every data-driven role. Because the split methods, filters, and column tools combine freely, the same app adapts to very different jobs.
Data Analysts and Engineers
Chunk multi-gigabyte exports into row-limited parts for tools that choke on huge files, create reproducible random shards for train/test/validation sets, and profile columns to catch dirty data before it breaks a pipeline.
Finance and Accounting
Break a year of transactions into monthly files by date, split a ledger by account or cost centre using column value, and remove duplicate rows from a reconciliation export before importing it into accounting software.
Marketing and CRM Teams
Segment a master contact list into per-region or per-segment files with the column-value method, filter to just the rows that match a campaign, and drop columns you should not share before handing a list to an agency.
Sales Operations
Split a national pipeline export into one file per territory so each rep gets only their accounts, then merge the returned files back into a single reporting CSV with source tagging.
Researchers and Academics
Divide a large dataset into equal parts for distributed processing, shard data reproducibly with a fixed seed, and keep a profiled data-quality report alongside the data for transparency.
IT and System Administrators
Cut oversized exports down to a size that clears an import cap, convert a comma-delimited file to semicolon-delimited on the way out, and standardize line endings between Windows and Unix systems.
Healthcare, Government, and Legal
Work entirely offline on sensitive records that must never be uploaded, split case or claim files by category or date, and profile for ragged rows before a compliance-critical import.
E-commerce and Retail
Split a product or order catalogue by category or by first letter, filter to a single brand or supplier, and rename or reorder columns to match a marketplace's required import format.
Real-World Workflows
Make a Huge Export Open in Excel
You have a 12-million-row export that Excel refuses to open. Load it on the Split tab, choose Number of Rows, set 1,000,000, run Preview to confirm the row count, and Start Split. You get twelve files that each open cleanly, every one carrying the header row.
Distribute Data by Region
A single national sales file needs to go to regional managers. Pick Column Value, choose the Region column, and the app writes one CSV per region. Add a simple filter first if you only want, say, the current quarter, and use Keep Only These Columns to omit internal fields before distribution.
Prepare a Machine-Learning Dataset
You need reproducible train/validation/test files. Choose Random Shards, set the number of files, and keep the default seed so the split can be reproduced exactly. Turn on Add Row Number if you need a stable identifier, and profile the source first to confirm there are no ragged rows.
Reassemble and Clean Split Parts
After processing individual parts, switch to the Merge tab, add the files, and combine them into one CSV with a single header. Tick the options to tag each row with its source filename, remove duplicates across all files, and sort the result by a key column.
Convert Format While You Split
A downstream system wants semicolon-delimited, CRLF-terminated files. Set the Output Delimiter to semicolon and the Line Ending to CRLF, then split by size to stay under the import cap. One pass both splits and reformats, with no separate conversion step.
Best Practices and Tips
Always Preview First
Run Preview before a big job. The row count, column list, and ragged-row warnings tell you whether the file is what you expected and roughly how many output files you will get.
Profile Messy Files
If a file has ever caused an import to fail, run it through the Profile tab first. Ragged-row counts and per-column stats surface the exact problem before you split.
Trust Auto-Detection, Verify When Odd
Leave delimiter and encoding on Auto for normal files. If preview output looks garbled, override the encoding manually - a sign detection was thrown off by an unusual file.
Keep Free Disk Space
Because output is written to disk rather than held in memory, make sure the output drive has room for the parts - and more if you also create a bundled archive.
Use a Fixed Seed for Reproducible Shards
When random shards need to be repeatable across runs or machines, keep the same seed. It guarantees identical assignment every time, including after a resume.
Filter and Trim Before You Split
Apply a simple filter and Keep Only These Columns to shrink the data first, so every output file is already scoped and free of fields you do not need.
Scope and Limitations
Being clear about the boundaries helps you decide whether it fits your workflow.
- It works with CSV and delimited text only - there is no XLSX, JSON, or database input or output. This single-format focus is what keeps it fast and simple.
- Row-based splitting is capped at 1,000,000 rows per output file, which keeps every part within Excel's row ceiling.
- The parallel worker slider speeds up compressing many output parts; the row-by-row read and write itself is a streaming operation.
- Output is written to disk, so you need enough free space on the output drive for all the parts (and any archive).
- The advanced filter evaluates a Python expression against each row, which is powerful but assumes you can write a small expression when you use it; the simple filter needs no coding at all.
Turbo CSV Splitter vs. Manual Methods
| Task | Manual / Spreadsheet Approach | Turbo CSV Splitter |
|---|---|---|
| Open a 10 GB CSV | Freezes or refuses to open in Excel | Streams row by row; never loads the whole file into memory |
| Split into 1M-row files | Copy-paste in chunks, error-prone and slow | One setting, one click, header on every part |
| One file per category | Manual filtering and Save As, repeated per value | Column Value method writes them all in a single pass |
| Monthly files from a date column | Sort, filter, and export month by month | Date method groups by day, month, or year automatically |
| Resume an interrupted job | Start over from the beginning | Checkpoint resumes exactly where it stopped |
| Reassemble parts | Paste files together, duplicate headers to clean up | Merge tab writes one header and can dedupe and sort |
| Spot data-quality issues | Eyeball the data and hope | Profile tab reports stats and flags ragged rows |
| Keep data private | Web splitters require uploading the file | 100% offline; nothing leaves your computer |
Safety and Reliability
- Checkpoint & Resume - a small checkpoint file is written to the output folder during every split job, so a cancelled or crashed run can resume from where it stopped.
- Fingerprinted Checkpoints - a checkpoint only resumes when the input file and settings match; if anything changed, the job starts fresh instead of applying stale progress.
- Ragged Row Handling - rows with a different number of fields than the header are padded or truncated safely and flagged in Preview and Profile rather than crashing the job.
- Fail-Open Filtering - if an advanced filter expression errors on a row, that row is kept rather than silently dropped, so a typo in a filter can't quietly delete data.
- Atomic Checkpoint Writes - checkpoint files are written to a temporary file and swapped in, avoiding a corrupted resume state if the app is closed mid-write.
- Stable Under Heavy Loads - streaming reads and writes keep memory use flat, even across files with tens of millions of rows.
- Ideal for Sensitive Environments - analytics teams, finance and ops teams, data engineers, and air-gapped networks working with exported CSV data.
Performance and Speed
Streaming, Not Loading
Rows are read and written one at a time, so memory use stays flat regardless of file size - no pandas-style full-file load into RAM.
Real-Time Rows/Sec & ETA
The status bar shows live throughput in rows per second and a dynamically updated estimated time remaining while a split or merge job runs.
Parallel Compression
When compression is enabled, output parts are compressed across up to 128 workers in parallel instead of one at a time.
External Merge-Sort
Sorting by column uses a chunked, disk-backed merge-sort so files far larger than available RAM can still be sorted correctly.
Fast Delimiter/Encoding Detection
Detection samples only the first portion of the file rather than scanning the whole thing, so even huge files open quickly.
Massive File Capability
Suitable for exported database dumps, analytics logs, e-commerce catalogs, survey data, and multi-gigabyte CSV exports from other systems.
Security and Privacy
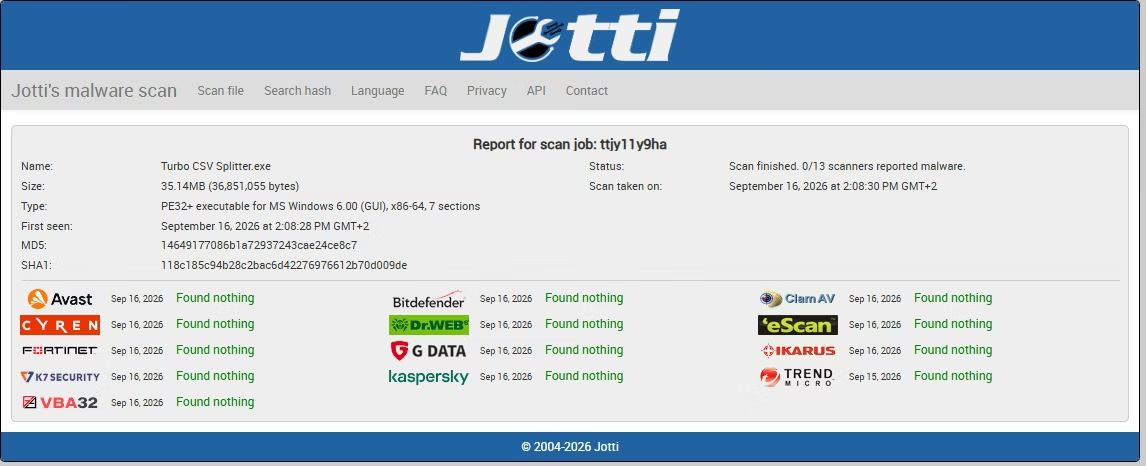
Turbo CSV Splitter is a fully local desktop application. All splitting, merging, and profiling happens on your own computer. No files are uploaded, scanned remotely, or shared with third parties. It is a trusted offline CSV splitter for personal, business, and enterprise data workflows.
- Does not log, analyze, track, or store the contents of your CSV files
- No integration with third-party analytics, advertising trackers, or background telemetry
- Internet is used only for license validation - the request contains no file names or file content
- Ideal for analysts, data engineers, businesses, and teams handling exported or sensitive data
- Complete confidentiality for personal, professional, and commercial workflows
Minimum System Requirements
| Operating System | Windows 8 (64-bit) |
| Processor | 1-2 CPU cores |
| Memory | 2 GB RAM |
| Storage | Free disk space at least equal to the size of your split or merge output |
Recommended System Requirements
| Operating System | Windows 10 or later (64-bit) |
| Processor | 4 or more CPU cores |
| Memory | 8 GB RAM or more |
| Storage Type | SSD recommended for best throughput on large files |
| Free Disk Space | Enough headroom for input, output, and temporary sort files |
App Info
| App Name | Turbo CSV Splitter |
| Version | 1.1 |
| Platform | Windows 10, Windows 11 |
| Category | Data Tools / CSV Utilities |
| Interface | Light desktop theme, four tabs (Split, Merge, Profile, Help) |
| Supported Format | CSV and delimited text (CSV-only edition) |
| Split Methods | 9 (rows, size, column value, date, alphabet, duplicates, unique, equal parts, random shards) |
| Processing | 100% offline / local, streaming engine |
| License Management | Gumroad |
Getting Started and Licensing
Turbo CSV Splitter is a standalone Windows program - no browser, no account, no background service. Setup takes a minute, and after a one-time activation it runs entirely offline.
1. Install and Open
Download from the Gumroad product page, install, and launch. The app opens on the Split tab, ready for you to point it at a CSV file.
2. Activate Your License
Enter the email you purchased with and your license key. The key is verified once against Gumroad and then cached locally, so you are not asked again on future launches.
3. Work Offline
Once activated, no internet connection is needed. Every split, merge, and profile runs on your own machine, keeping sensitive data entirely local.
4. Check for Updates
The app links back to its Gumroad page, where the latest version is always available to download if you ever need to update.
A Fast, Reliable CSV Splitter for Windows
Turbo CSV Splitter is a dedicated CSV splitter, CSV merger, and column profiler built for large, unwieldy CSV exports. It processes everything locally on your computer - no uploads, no cloud services, no file-size limits, no waiting queues - making it ideal for data analysts, developers, e-commerce teams, and anyone who regularly hits Excel's 1,048,576-row wall. As a complete csv file splitter for Windows 11 and Windows 10, it supports splitting by row count, file size, column value, date, alphabet, duplicate status, equal parts, or random shards, so you can split a CSV by rows for spreadsheet-friendly chunks, split a CSV by column for one-file-per-category exports, or generate random shards for machine-learning train/test/validation splits. Everything streams row by row rather than loading the whole file into memory, so multi-GB and 100 GB+ CSV files are supported as long as there's enough free disk space for the output. It's also a full-featured CSV merge tool and CSV column profiler in one lightweight desktop install, with no separate scripts, notebooks, or web apps required.
Looking for other batch data or file tools from TurboSoft? Million by Million Rows Copier moves huge spreadsheet ranges to the clipboard in chunks, and the Bulk Renaming Tool cleans up filenames across thousands of files in one pass.
Behind the simple interface is a careful engine: streaming reads and writes keep memory flat on files of any size, fingerprinted checkpoints make long jobs safely resumable, an advanced filter that errors on a row keeps that row rather than silently dropping data, and every split part is written with its header intact so it stands on its own. Whether you need to split a large CSV into smaller files for Excel, break an export into one file per category or per month, shuffle rows into reproducible shards for a model, or simply profile a file to find the bad rows before they break an import, this csv file splitter turns an unwieldy CSV into clean, predictable output - quickly, privately, and entirely on your own computer. Grab the csv splitter download from Gumroad and turn your next oversized export into a set of files you can actually work with.
Frequently Asked Questions
Common Questions About Turbo CSV Splitter
Is Turbo CSV Splitter a good csv file splitter for very messy exports?
Yes. As a csv file splitter, it auto-detects delimiter and encoding, flags ragged rows during Preview, and lets you filter or clean columns before splitting - so a messy export gets split cleanly instead of producing broken output files.
Where do I get the csv splitter download?
The csv splitter download is available directly from the Buy Now button on this page and links to the Gumroad product page. After the csv splitter download finishes, install it, activate your license once, and it works fully offline from then on.
How do I split a CSV file that's too big for Excel?
Open Turbo CSV Splitter, browse to your CSV file, choose Number of Rows as the split method, set rows per file (up to 1,000,000), and click Start Split. Excel's 1,048,576-row limit is never hit because each output file stays under your chosen size.
Can it split a CSV file by column value?
Yes. Choose the Column Value split method and pick a column - Turbo CSV Splitter writes one output CSV per distinct value in that column, so you could split a sales file into one file per region or per customer automatically.
Does it work on huge multi-gigabyte CSV files?
Yes. Turbo CSV Splitter streams the file row by row instead of loading it into memory, so multi-GB and 100 GB+ CSV files are supported as long as there's enough free disk space for the output.
Can I merge split CSV files back into one?
Yes. The Merge tab combines two or more CSV files back into a single file, writing the header only once. You can optionally tag each row with its source filename, remove duplicate rows, and sort the combined result by a column.
What happens if a split job is interrupted?
Turbo CSV Splitter saves a checkpoint file in the output folder. If a job is cancelled or the app crashes partway through, clicking Start Split again with the same file and settings resumes exactly where it left off instead of starting over.
Can it split CSV files by date?
Yes. The Date Column split method groups rows by day, month, or year based on a date column you select, automatically parsing common date formats and writing one file per time bucket.
Does it detect the CSV delimiter and encoding automatically?
Yes. Delimiter and text encoding are set to Auto by default, and Turbo CSV Splitter samples the file to detect comma, semicolon, tab, or pipe delimiters and common encodings like UTF-8, UTF-8 with BOM, UTF-16, CP1252, and Latin-1.
Can I remove duplicate rows while splitting?
Yes. Turn on Remove Duplicate Rows to drop exact duplicates (compared across all columns) before the file is split, or use the dedicated Duplicate Values and Unique Values split methods to separate duplicates from first-seen rows.
Is there a tool to check data quality before splitting a CSV?
Yes. The Profile tab scans a CSV and reports, per column, non-null and blank counts, distinct value counts, min/max text length, and numeric min/max/mean - plus it flags ragged rows that have a different number of fields than the header.
Can it split a CSV that is larger than my available RAM?
Yes. Turbo CSV Splitter streams the file one row at a time and never loads the whole thing into memory, so file size is limited by free disk space for the output rather than by how much RAM you have. Multi-gigabyte and 100 GB+ files are supported.
Does every output file include the header row?
Yes, when the file has a header. Each split part is written with the header at the top so it is independently valid and opens correctly on its own, without you having to copy headers between files.
What is the maximum number of rows per output file?
The row-based split method is capped at 1,000,000 rows per file, which keeps every part comfortably within Excel's 1,048,576-row limit. If you need larger parts, use the file-size method instead.
Can I split one CSV into a file per value in a column?
Yes. Choose the Column Value method and pick the column. The app writes one output CSV per distinct value found in that column - for example one file per region, per customer, or per product category.
Can I split by date - one file per month or year?
Yes. The Date Column method groups rows by day, month, or year based on a date column, parsing common date formats automatically. A year of records can become twelve monthly files in a single pass.
Can I create reproducible random splits for machine learning?
Yes. The Random Shards method assigns every row to one of N files at random, and it uses a fixed seed, so the same seed always produces the same assignment - even if you cancel and resume. That makes train/test/validation splits fully reproducible.
Can I merge CSV files back together?
Yes. The Merge tab combines two or more CSV files into one, writing the header only once. You can optionally tag each row with its source filename, remove duplicate rows across all files, and sort the merged result by a column.
Can I filter rows so only some end up in the output?
Yes, two ways. A simple filter lets you pick a column, an operator such as equals, contains, starts with, greater than, or is blank, and a value - no coding. An advanced filter accepts a small Python expression using the row dictionary, and runs in addition to the simple filter.
Can I remove or rename columns during a split?
Yes. Keep Only These Columns whitelists the columns to keep, Drop These Columns removes specific ones, and Rename Columns changes header names using old:new pairs - all without altering which data goes where.
Can I remove duplicate rows while splitting?
Yes. Turn on Remove Duplicate Rows to drop exact duplicates, compared across all columns, before the file is split or merged. There is also a dedicated Unique Values split method that keeps only the first occurrence of each row.
Can I sort a huge file before splitting without running out of memory?
Yes. Sort by Column uses a chunked external merge-sort, so even very large files can be sorted ascending or descending without exhausting RAM.
Can I compress the output files?
Yes. You can leave parts uncompressed, zip or gzip each part individually, or bundle every part into a single ZIP or gzip archive. Compressing many parts is sped up by the parallel worker slider.
Can I change the delimiter or line ending on output?
Yes. Leave the Output Delimiter blank to match the input, or set a different one to convert - for example comma in, semicolon out. You can also choose the quoting style and switch the line ending between LF and CRLF.
What happens if a split job is interrupted?
The app saves a small checkpoint file in the output folder. If the job is cancelled or the app closes partway through, running Start Split again with the same input file and settings resumes exactly where it left off instead of starting over.
Does it work completely offline?
Yes. All reading, splitting, merging, and profiling happen locally on your PC. Nothing is uploaded, which makes it suitable for confidential and regulated data. The only internet use is a one-time license check.
How is Turbo CSV Splitter licensed?
It is licensed through Gumroad. Activate once with your purchase email and license key; the license is then cached locally so you are not asked again on future launches, and the tool keeps working offline.
Which operating systems are supported?
It is a Windows desktop application built with a light, native-feeling interface. It runs on Windows 10 and Windows 11 and does not require any browser or online account.
Do I have to configure the delimiter and encoding myself?
No. Both default to Auto. The app samples the file to detect comma, semicolon, tab, or pipe delimiters and common encodings such as UTF-8, UTF-8 with BOM, UTF-16, CP1252, and Latin-1. You only override them if detection gets it wrong.